←搜索结果

按匹配度 · 共 564 条结果 清除搜索

星期二

  1. OpenAI:部署安全与系统卡

    OpenAI 发布 gpt-oss-120b 与 gpt-oss-20b 模型卡

    OpenAI 发布 gpt-oss-120b 和 gpt-oss-20b 两个开放权重推理模型,采用 Apache 2.0 许可,兼容 Responses API,支持工具调用、完整 CoT 与可调推理强度。gpt-oss-120b 为 36 层 MoE 架构,116.8B 总参数、5.1B 激活参数,MoE 权重以 MXFP4 量化后可放入单张 80GB GPU;gpt-oss-20b 为 24 层、20.9B 总参数、3.6B 激活参数,可在 16GB 内存设备上运行。OpenAI 对 gpt-oss-120b 做了对抗性微调测试,其安全咨询组认为即便使用其训练栈进行微调,模型也未在生物化学与网络安全两个类别达到 Preparedness Framework 的高能力阈值。

    Figure 1. <em>Main capabilities evaluations</em>. We compare the gpt-oss models
at reasoning level <code>high</code> to OpenAI’s o3, o3-mini, and
o4-mini on canonical benchmarks. gpt-oss-120b surpasses OpenAI o3-mini
and approaches OpenAI o4-mini accuracy. The smaller gpt-oss-20b model is
also surprisingly competitive, despite being 6 times smaller than
gpt-oss-120b. <em>*Note:</em> o3-mini was evaluated on AIME without
tools, see Table <a class="xref-link" data-xref="tab:all_evals" href="/gpt-oss/full-evaluations#tab:all_evals">3</a> for the gpt-oss
models on AIME without tools

    d our gpt-oss usage policy. Developed with feedback from the open-source community, these text-only models are compatible with our Responses API and are designed to be used within agentic workflows with strong instruction following, tool use like web search and Python code execution, and reasoning capabilities—including the ability to adjust the reasoning effort for tasks that don’t require complex reasoning. The models are customizable, provide full chain-of-thought (CoT), and support Structure

    匹配字段正文
  2. OpenAI:部署安全与系统卡精选

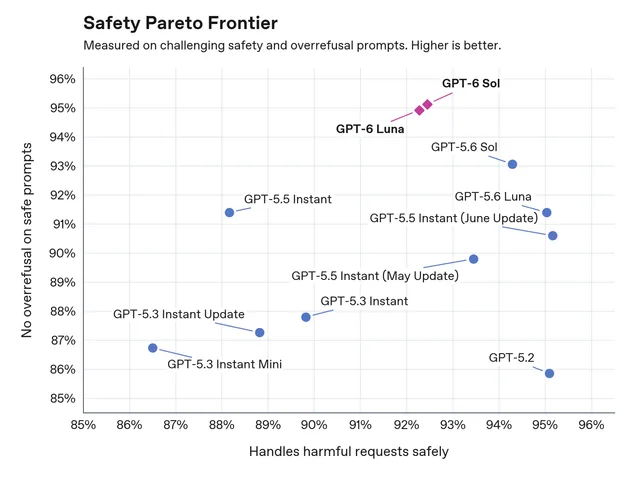
    OpenAI 发布 GPT-6 Sol 与 GPT-6 Luna 系统卡

    OpenAI 在 ChatGPT 免费与付费方案中向全球用户推出 GPT-6,取代 GPT-5.6 Sol 和 GPT-5.6 Luna,Codex 与 ChatGPT Work 中仍使用此前版本。系统卡显示,GPT-6 对越狱(含多轮自适应攻击)的抵抗力更强,不诚实、欺骗和绕过护栏的行为减少,指令层级评测中 GPT-6 Sol 与 Luna 分别达到 99.99% 和 99.79% 的稳健性。同时 GPT-6 Sol 在标准自我伤害类别出现统计显著回退,GPT-6 Luna 在自我伤害、血腥和性内容上出现回退,OpenAI 称人工复核后违规程度总体较低。按 Preparedness Framework,两款模型在网络安全和生物化学领域被列为 High capability,均未达到 AI 自我改进的 High 阈值。

    Figure 1. Safety and non-overrefusal on challenging prompts. Higher is better
on both axes.

    propriate safeguards, and improving how we measure and report model performance for younger users. 3.2 Vision We ran the image input evaluations originally introduced with ChatGPT Agent. These tests use disallowed requests that combine text and images and measure whether the model’s responses are classified as safe. GPT‑6 Sol (October) and GPT‑6 Luna (October) performed on-par with GPT-5.6 Sol (August) and GPT-5.6 Luna (August), respectively, except for a regression on the extremism vision evalu

    匹配字段正文

  3. OpenAI:部署安全与系统卡

    OpenAI 发布 GPT-6 Astra 系统卡

    OpenAI 发布 GPT-6 Astra 系统卡,宣布这是其迄今能力最强、已广泛部署的模型,也是首个在 Preparedness Framework 下达到网络安全 Critical 等级的模型。系统卡称 Astra 对越狱和提示注入的鲁棒性显著强于 GPT-5.6 Sol,间接提示注入鲁棒性从 96.23% 升至 99.79%,在 54,218 个内部 Codex 任务模拟中严重度 3 级及以上的错位行为标记减少约 53%。同时 OpenAI 指出 Astra 的 CoT 可监控性相对 GPT-5.6 Sol 下降,在对抗条件下可能规避内部监控,因此将错位监控扩展到全部工具调用推理。

    Figure 1

    des performance information for GPT-6 Astra on the new, updated versions; September 29, 2026: We added an Appendix: dots with information about dots, remarkably capable, always-on agents built to handle everything. Dots are built on existing model and agent capabilities, powered by GPT-6 Astra 1. Safety Overview: GPT-6 Astra Today, we are releasing GPT-6 Astra, the most capable model we have ever broadly deployed. Astra is our first model to reach the Critical level of cybersecurity capability u

    匹配字段正文

  4. OpenAI:部署安全与系统卡精选

    OpenAI 发布 GPT-6.1 Sol 系统卡增补:安全评估与 GPT-6 Astra 对比

    OpenAI 发布 GPT-6.1 Sol,称其能力接近 GPT-6 Astra,兼顾速度与成本,并按 Preparedness Framework 将其网络安全定为 Critical、生物化学定为 High,沿用与 Astra 相同的防护措施。系统卡显示,GPT-6.1 Sol 在 Production Benchmarks 的八个类别中有五个高于 GPT-6 Sol,在 HealthBench 四项评测中与 GPT-6 Astra 差距在 0.5 个百分点以内,且未尝试绕过监控。在内部 Codex 流量部署模拟中,其严重度 3 级及以上的错位行为标记为 28 个(0.056%),低于 GPT-6 Sol 的 42 个和 GPT-5.6 Sol 的 63 个。

    18 evaluations (higher is better) GPT‑6.1 Sol scores higher than GPT‑6 Sol in five of six categories; the regression on the gore evaluation is not statistically significant. 3.1.3 Agentic Safe Completions Table 3: Agentic Safe Completions (higher is better) We find that GPT-6.1 Sol is generally better than GPT-6 Sol at recognizing potential harms in agentic requests and avoiding taking harmful actions. 3.2 Vision Table 4: Image input evaluations, with metric safe completion (higher is better) Ac

    匹配字段正文

  5. OpenAI:部署安全与系统卡精选

    OpenAI 发布 GPT-5.6 八月更新系统卡

    OpenAI 更新 ChatGPT 默认模型,免费与 Go 用户获得新的日常对话默认模型,Plus 和 Pro 用户获得带 effort 滑块的 GPT-5.6 Sol,这些模型将取代 GPT-5.5 Instant;Codex 与 ChatGPT Work 中的 GPT-5.6 Sol 和 GPT-5.6 Luna 仍为 7 月版本。按 Preparedness Framework,本次 8 月版 GPT-5.6 Sol 和 GPT-5.6 Luna 在网络安全与生物化学两个领域均被定为 High 能力,AI 自我改进未达 High 阈值,并沿用 GPT-5.6 系统卡中的防护措施。系统卡首次纳入面向 18 岁以下用户的 U18 专项评测,覆盖自残、饮食失调、年龄限制商品与服务、暴力内容和不当性内容等场景;GPT-5.6 Sol 与 Luna 在这些类别表现良好,与 GPT-5.5 变体相比无统计显著差异。

    Figure 1

    otein engineering) were asked to transcribe biological protocols they have personally used in the lab. Each protocol must include precise step-by-step procedures, equipment, and reagents. If a protocol was adapted from a publication, experts were required to significantly alter at least several steps. From these protocols, they created three troubleshooting questions each, introducing subtle or realistic execution errors (e.g., improper homogenization technique) and describing the resulting fail

    匹配字段正文

  6. Latent Space精选

    Meta MSL 发布 Muse Wonder 与 Muse Wonder Full 模型

    Meta Superintelligence Labs 发布第二代模型家族 Muse Wonder 与 Muse Wonder Full,前者定位快速前沿模型,后者为完整版本,Meta 称其面向个人与专业智能体工作。Artificial Analysis 的 Intelligence Index v4.3 中 Wonder Full 得 56 分、Wonder 得 52 分,高于 Muse Spark 1.3 的 48 分,Opus 5.5 以 58 分领先。规格为 1M 上下文,输入支持文本、图像、视频和音频,输出仅文本,定价为每百万 token 输入 4 美元、缓存输入 0.20 美元、输出 20 美元。

    a Model API and Muse Code. Muse Code installs with curl dev.meta.ai/install.sh | bash (@alexandr wang). Positioning. Meta pitches the models as SOTA for “personal and professional agentic work.” @alexandr wang named three headline features: Active Memory: memory across days, weeks and months. Active Focus: working through blockers to finish tasks. Domain expertise: SOTA in finance and legal, “strong in health.” Training story. Wang says Meta continued scaling both pre-training and RL since Muse

    匹配字段正文

  7. The Elec

    Meta 发布 Muse Wonder 系列模型,主打 Active Memory 与 Active Focus

    Meta 于 10 月 13 日发布前沿模型 Muse Wonder 系列,包含 Muse Wonder 和 Muse Wonder Full 两个版本,均仅通过每月 50 美元或 200 美元的付费订阅提供。Muse Wonder 可通过 SDK 或按量付费 API 供开发者接入,Muse Wonder Full 无对外 API 或 SDK,仅限 Meta 自有环境使用,更适合长周期复杂任务。该系列主打 Active Memory 与 Active Focus 两项能力,前者主动保留历史对话与用户上下文,后者在任务受阻时尝试替代方案。在 Artificial Analysis 评测中,Muse Wonder Full 在 CritPt 科学推理测试和 GDP.pdf 专业文档基准中排名第一,Terminal-Bench 4.0 得分从上一版的 33% 升至 57%;Intelligence Index 上 Muse Wonder 得 52 分、Muse Wonder Full 得 56 分,后者与 Claude Sonnet 5.5 并列第二。AA 称两款模型输出 token 用量比 Muse Spark 少约 10%,Muse Wonder Full 输入 token 比 Muse Wonder 少 16%。Muse Wonder 定价为每百万输入 token 4 美元、每百万输出 token 20 美元。

    ; Reply 0 Meta Platforms announced Oct. 13 that it has unveiled its latest frontier artificial intelligence (AI) models, the Muse Wonder series, featuring major improvements in AI agents' ability to independently handle complex tasks. The series comprises two versions, Muse Wonder and Muse Wonder Full. The models are differentiated by their availability to external developers and their use within Meta's proprietary work environment. Both are available only through paid subscriptions priced at $5

    匹配字段正文

  8. 虎嗅

    Meta 发布 Muse Wonder 与 Muse Wonder Full,长程编程测试超过 Claude…

    Meta Superintelligence Labs 于 10 月 13 日推出新一代旗舰模型 Muse Wonder 和 Muse Wonder Full,Full 版在 Artificial Analysis 综合智能指数得 56 分,距 Claude Opus 5.5 的 58 分差 2 分。在 DeepSWE 1.1 长程软件工程测试中,Wonder Full 取得 79.0 分,超过 Opus 5.5 的 74.2 分和 GPT-6 Astra 的 74.1 分,但 Terminal-Bench 4.0 和 ProgramBench 仍落后于 Opus。Artificial Analysis 测算其平均任务成本达 4.52 美元,较上代 Muse Spark 1.3 上涨 183%;开发者同题对比显示其 3D 游戏生成效果明显逊于 Opus,Meta 模型卡已承认 3D 任务为已知局限。

    [[ Meta新旗舰模型Muse Wonder在长程编程等Agent测试中超越Claude Opus 5.5,综合智能指数逼近第一梯队,但推理成本大涨183%,且3D生成实测表现不佳,暴露视觉空间推理短板。 要点 1. 旗舰跑分挤进第一梯队,长程编程领先 Wonder Full综合智能指数56分,距Claude Opus 5.5仅差2分;DeepSWE 1.1长程软件工程测试中取得79.0分,超过Opus 5.5的74.2分和GPT-6 Astra的74.1分,在10项测试中有6项跻身前三。 2. 换用新预训练底座,针对Agent能力优化 Wonder内部代号Watermelon,采用独立更大规模预训练并引入Active Memory与Active Focus机制,从底层增强模型的长期记忆、持续执行与任务泛化能力,而非像Spark系列那样仅依靠后续强化学习迭代。 3. 推理成本大幅上涨,颠覆性定价策略引发质疑 Wonder任务平均成本达4.52美元,较上代Spark 1.3上涨183%,比GPT-6 Astra高39%;官方虽小幅降低按Token计费价格,但Full版本的订阅额度消耗异

    匹配字段正文

  9. 虎嗅精选

    Meta发布Muse Wonder系列模型,主打个人智能体记忆与长程任务

    Meta发布Muse Wonder和Muse Wonder Full两款模型,内部代号西瓜,主攻个人与专业智能体任务,重点提升跨对话记忆和长时间任务执行能力。Artificial Analysis评测显示Wonder Full十项测试有六项进入前三,最高推理强度下Muse Code搭配Wonder Full的编程成绩与Claude Code搭配Sonnet 5.5持平。API定价为每百万输入token 4美元、输出20美元,Wonder Full仅向Muse Code订阅用户开放,Meta AI负责人Alexandr Wang承认编程能力仍不如Opus 5.5。

    r Full新模型至少在部分基准测试上,已能与GPT-6 Astra和Claude Fable 5.1掰手腕。 第三方机构Artificial Analysis的测试也显示,Wonder Full较上一代脱胎换骨,在多项智能体和专业工作评测中跻身前三甲。 花大价钱攒起来的队伍,让Meta重新有了跟领先模型叫板的底气,也让Meta Muse的Personal Agent之路能走得更顺畅些。 Meta此次发布,延续了一年多来对AI业务的重整。 2025年4月,Llama 4马失前蹄,扎克伯格随即加大人才和算力投入,招揽Scale AI创始人Alexandr Wang,重组研究团队。今年4月,重组后的团队推出Muse Spark,但与竞争对手相比仍差着一口气。 按照Meta的说法,过去14个月里,团队推倒重来,从底层重建技术体系,并持续扩大预训练和强化学习的规模。此次Wonder系列在吉瓦级Prometheus数据中心完成训练,成为这轮豪赌交出的最新筹码。 Muse Wonder围绕两个方向动刀,分别是Active Memory和Active Focus。 Active Memory负责跨对

    匹配字段正文

  10. AI at Meta精选

    Meta 发布 Muse Wonder 系列模型,主打个人与专业智能体任务

    Meta 发布 Muse Wonder 和 Muse Wonder Full 两款前沿模型,称其在个人与专业智能体、记忆和编码等关键基准上取得 SOTA。Muse Wonder 即日起通过 Meta Model API 和 Muse Code 提供,Muse Wonder Full 面向 Muse Code 订阅用户;Muse Wonder 还将接入个人智能体产品 Muse,先向订阅用户开放。两款模型引入 Active Memory 跨对话保留上下文,以及 Active Focus 在任务受阻时尝试替代方案并坚持完成目标。

    The Muse Wonder series achieves state-of-the-art results across key benchmarks for personal and professional agents, memory, and coding. Muse Wonder and Muse Wonder Full apply specialized knowledge to problems people encounter at work and in daily life, from understanding a lease to making sense of financial or health information. Our evaluations include tasks in law, finance, and health that test this ability.

    匹配字段正文

  11. AI at Meta精选

    Meta 发布 Muse Wonder 与 Muse Wonder Full 两款前沿模型

    Meta 发布 Muse Wonder 系列,包含 Muse Wonder 和 Muse Wonder Full 两款前沿模型,面向个人与专业智能体任务。Muse Wonder 即日起通过 Meta Model API 和 Muse Code 提供,Muse Wonder Full 面向 Muse Code 订阅用户开放,Muse Wonder 后续还将接入个人智能体产品 Muse,先向订阅用户推送。两款模型引入 Active Memory 跨对话保留上下文、Active Focus 在任务受阻时尝试替代方案并推进到完成,官方称其在个人与专业智能体、记忆和编码基准上取得 SOTA 结果。

    We’re excited to introduce the Muse Wonder series with Muse Wonder and Muse Wonder Full, our most capable models yet. Both are frontier models, built to deliver state-of-the-art performance for personal and professional agentic tasks.

    匹配字段正文

星期一

  1. MarkTechPost

    Cloudflare 发布 Clef-omni:30B-A3B 多模态决策模型

    Cloudflare 发布开源权重多模态决策模型 Clef-omni,可在一次调用中对文本、图像、音频和视频打分,基于 Qwen3-Omni-30B-A3B-Instruct 后训练,采用 30B 总参数、3B 激活参数的 MoE 结构,Apache-2.0 许可,定价每百万 token 0.15 美元。它在意图分类任务上领先,CLINC150+OOS 达 97.7 macro-F1,但在推理与工作流评测上落后于 Clef,GPQA Diamond 为 47.4,而 Jev 为 78.3。同批更新将 Clef-flash 价格降至 0.038 美元,并把托管 Clef 迁移到 SGLang,中位延迟从 262 ms 降至 152 ms。

    same update cut Clef-flash pricing below TypeSafe’s Jev and made hosted Clef roughly 2x faster. For developers, this removes the transcription and captioning steps that multimodal agent pipelines usually need. TL;DR Size: 30B total, 3B active parameters (MoE); 64,000-token context on Workers AI; Runs on: Workers AI as @cf/cloudflare/clef-omni; self-hosting tested on a single H200, about 64 GB GPU memory in bfloat16; Performance: Close to Clef on routing and intent tasks, behind it on most reason

    匹配字段正文

星期日

  1. MarkTechPost

    OrcaRouter 发布 OrcaCyber Zero 1.5 安全模型,支持 1M 上下文

    OrcaRouter 发布 OrcaCyber Zero 1.5,这是 OrcaCyber Zero 1.0 的后继模型,面向授权漏洞复现、漏洞利用开发和渗透测试,支持 1M token 上下文窗口、原生函数调用和结构化输出。厂商自报成绩为 Cybench 100%(39/39,无限制智能体执行)、CVE-Bench 95.8%(24 个可评估任务中的 23 个)、HumanEval+ 93.9%、SWE-bench Pro V2 76.5%。模型仅通过 OrcaRouter 托管 API 提供,使用 OpenAI 兼容接口,base_url 为 https://api.orcarouter.ai/v1,调用 orca/orcacyber-zero-1.5,访问受 Security Research 层级限制,定价为每 1M 输入 token 3.00 美元、每 1M 输出 token 7.50 美元。

    d variants, hardware not disclosed; Performance: Vendor-reported scores are near ceiling on cyber benchmarks and strong on coding; Best: 100% on Cybench (39/39 tasks, unrestricted agent execution); Worst: 76.5% on SWE-bench Pro V2, its lowest published score; Bottom line (best): Top-tier cyber scores at $3.00 / $7.50 per 1M tokens; Bottom line (worst): Every number is self-reported, and CVE-Bench used only 24 evaluable tasks What is OrcaCyber Zero 1.5? OrcaCyber Zero 1.5 is a frontier cybersecur

    匹配字段正文

  2. Thinking Machines Lab:官方博客精选

    Thinking Machines Lab 发布开源权重模型 Inkling

    Thinking Machines Lab 发布从零训练的开源权重模型 Inkling,采用 MoE 架构,总参数 975B、激活 41B,支持最高 1M token 上下文窗口,预训练数据为 45 万亿 token 的文本、图像、音频和视频。该模型原生支持文本、图像和音频推理,并可通过可控思考力度平衡性能与 token 效率,今日起在 Tinker 上开放微调,完整权重已上传 Hugging Face。官方同时预览了 12B 激活参数的轻量版 Inkling-Small,称其在多项基准上接近或超过 Inkling,测试完成后将发布完整权重。

    owcase what Inkling can do and how it measures up on important qualities such as trustworthiness and safety. Generalist model Inkling is designed to be broad. We trained it across agentic, reasoning, coding, instruction-following, factuality, vision, and audio tasks, rather than narrowly optimizing for one domain. That breadth matters for customization and real-world use: different users need models that can adapt to very different workflows, not just excel on benchmarks. Agentic coding and tool

    匹配字段正文

  3. Thinking Machines Lab:官方博客精选

    Thinking Machines Lab 发布开源权重模型 Inkling-Small

    Thinking Machines Lab 发布开源权重模型 Inkling-Small,采用 MoE 架构,总参数 276B、激活 12B,在四分之一体量下达到与 Inkling 相当的性能。该模型原生支持音频与图像推理、可变思考力度和最高 1M token 上下文窗口,在 HLE 上得分 31.6%,超过 Inkling 的 29.7%,SWE-bench Verified 超过 80%。完整权重已开放,并可在 Tinker 上微调,在 Tinker Playground 进行文本、图像和音频对话。

    and well-rounded performance across a range of benchmarks. Inkling-Small Inkling Compared to Inkling, Inkling-Small achieves comparable performance with much less compute. Across agentic tool use (Terminal-Bench 2.1), reasoning (HLE text-only, no tools), and instruction following (IFBench) benchmarks, Inkling-Small is more efficient than Inkling and competitive with other models in its weight class. Furthermore, its variable thinking effort lets users easily adapt it to target their use case, b

    匹配字段正文

  4. Reflection Blog精选

    Reflection 发布首个开放权重模型 Beam:501B 参数 MoE,主打编码与智能体

    Reflection 发布首个开放权重模型 Beam,采用稀疏 MoE 架构,总参数 501B、激活 23B,面向编码、推理和智能体任务。该模型在 23.8 万亿 token 上预训练,并用 10.5K NVIDIA GB300 GPU 进行四周高算力 RL,生成超 1 亿条 rollout。Reflection 表示 Beam 在编码和智能体任务上可与 GLM 5.2 竞争、接近 Qwen 3.8-Max,优势在于推理效率,本月将以 Apache 2.0 协议发布权重、技术报告和模型卡。

    ducing Beam, Reflection’s first open-weight model. Beam is a sparse Mixture-of-Experts model with 501 billion total parameters, 23 billion active, built for coding, reasoning, and agentic workloads. Beam’s capabilities come from major investments in both pretraining and reinforcement learning (RL). We pretrained the model on 23.8 trillion diverse, curated, high-quality tokens from the web and proprietary licensed datasets, matching or outperforming available similar-sized open base models. In pa

    匹配字段正文

星期六

  1. The Decoder

    微软发布 Decision-1 决策模型,基于 Qwen3.5-9B

    微软推出决策模型 Decision-1,基于 Qwen3.5-9B,面向分类、评估和路由决策,并称有潜力引导和控制智能体应对复杂环境。微软称其在覆盖 36 项基准、近 15 万个问题的测试中最准确,速度是第二名 H2O-Lightning-4B 的 2.5 倍。该模型已通过 Microsoft Foundry 和 OpenRouter 提供,输入 token 每百万 0.042 美元,输出 token 免费。

    on-1 is built for fast, structured decisions. According to Microsoft , it handles classifications, evaluations, and routing decisions and has "the potential" to "guide and control agents through complex environments." Decision-1 is based on Qwen3.5-9B. Microsoft says it's the most accurate model tested across 36 benchmarks covering nearly 150,000 questions. On speed, it's 2.5 times faster than the runner-up, H2O-Lightning-4B. Cloudflare's open-source Clef models, which are also based on Qwen, we

    匹配字段正文

  2. The New Stack

    微软在 Foundry 发布基于阿里 Qwen 的决策模型 Microsoft-Decision-1

    微软在 Foundry 上线 Microsoft-Decision-1,该决策模型基于阿里 Qwen3.5-9B 后训练而成,而非采用合作伙伴 OpenAI 的模型,定价为每百万输入 token 0.042 美元、输出免费。微软称其已在内部四个团队测试,用于整理超 1 万条 Xbox 玩家反馈、为 Copilot 打分、事故现场拉取上下文等场景,并称在 Xbox 场景下比 GPT-6 Sol 快 14 倍以上。该模型仅支持文本、上限 32,768 token 并返回 JSON,不支持图像,微软尚未公布开放权重。

    c.twitter.com/M3fAOD90r6 — Satya Nadella (@satyanadella) October 9, 2026 Xbox Research used it to sort more than 10,000 pieces of player feedback, the Copilot team graded chat and agent responses with it, on-call engineers used it to pull context during live incidents, and Microsoft Discovery used it to score experiments before an agent replans. Microsoft’s numbers show it’s more than 14 times as fast as GPT-6 Sol at a fraction of the cost for Xbox, and 46 times more consistent in Discovery. But

    匹配字段正文

  3. Apple Machine Learning Research精选

    Apple 发布第三代 Apple Foundation Models,含五款模型

    Apple 发布第三代 Apple Foundation Models(AFM),共五款模型,覆盖端侧与运行在 Private Cloud Compute 上的服务器模型。端侧包括 30 亿参数的 AFM 3 Core 和 200 亿参数、稀疏架构的 AFM 3 Core Advanced,后者每次仅激活 1 至 40 亿参数;服务器端包括 AFM 3 Cloud、图像模型 ADM 3 Cloud 和 AFM 3 Cloud Pro。评测显示 AFM 3 Core 在通用文本上获得 45.6% 的偏好率,AFM 3 Cloud 为 64.7%,AFM 3 Core Advanced 的语音合成 MOS 得分为 4.15。

    Hero

    unlocks advanced photo-editing tools, the all-new Image Playground, and more; AFM 3 Cloud Pro, our most capable server-based model, which powers our most demanding use cases, like agentic tool use and complex reasoning AFM 3 Core, AFM 3 Core Advanced, and AFM 3 Cloud, along with ADM 3 Cloud, are all purpose-built for Apple silicon. For AFM 3 Cloud Pro, we worked with Google and NVIDIA to extend Private Cloud Compute to NVIDIA GPUs in Google Cloud, while maintaining the same guarantees to protect

    匹配字段正文

  4. MarkTechPost

    Nace AI 开源 9B 决策模型 Drex 1.5,在 Decision Index 0.3.1 上得分 58.08

    Nace.AI 开源了 Drex 1.5,一个 8.95B 稠密决策模型,不生成文本,而是读取状态和带类型的问题后为每个选项返回概率,权重已发布在 Hugging Face,OpenRouter 上有托管版本。它在公开 Decision Index 0.3.1 上得分 58.08,与闭源模型 Jev 1.13.0 的 57.96 处于同一并列区间,在 37 项基准中有 20 项领先。模型默认上下文 16,384 tokens、最高 131,072,可在单张 24 GB A10G 上以 bf16 运行,Q8_0 GGUF 约 9.5 GB 可跑在 Apple 芯片和 CPU 上,但 GPQA Diamond 仅 45.4%、ACOS 情感分析 F1 仅 7.4%。

    Nace.AI has open-sourced Drex 1.5, a 9B decision model for agents and backend workflows. The Drex 1.5 decision model does not write text. It reads a state and typed questions, then returns a probability for every option. Nace reports 58.08 on the public Decision Index 0.3.1, the top score under 10B parameters. Weights are on Hugging Face, and a hosted version is live on OpenRouter. TL;DR Size: 8.95B parameters (dense), bf16 weights about 18 GB. Context is 16,384 tokens by default, up to 131,072;

    匹配字段正文