←搜索结果

按匹配度 · 共 564 条结果 清除搜索

星期六

  1. MarkTechPost

    微软发布 Microsoft-Decision-1:基于 Qwen3.5-9B 的决策打分模型

    微软发布 Microsoft-Decision-1,一个基于阿里 Qwen3.5-9B 后训练的决策打分模型,对固定选项返回校准后的概率而非生成文本,现已上线 Microsoft Foundry 和 OpenRouter。它支持 32,768 token 上下文,在微软 36 项基准对比中平均准确率 83.5%,p50 延迟 85 ms,输入定价为每百万 token 0.042 美元、输出免费。模型仅提供托管 API,不开放权重,且所有基准均为厂商自测。

    Microsoft has released Microsoft-Decision-1, a decision model for routing, classification, verification and agent control. Microsoft-Decision-1 is a decision-scoring model that returns a calibrated probability for each fixed answer option instead of generated text. It is post-trained from Alibaba’s Qwen3.5-9B and available now in Microsoft Foundry and OpenRouter. . TL;DR Size: Built on Qwen3.5-9B; exact parameter count not disclosed. 32,768-token context window; Runs on: Hosted API only (Microso

    匹配字段正文
  2. cnBeta

    Google Gemini 4 Pro 匿名现身 Arena 首测登顶

    一个以 gemini-3.8-flash 马甲现身的匿名模型在 Arena 盲测中被认为是 Google 的 Gemini 4 Pro,据称在多项基准上取得领先。文章称其在 DeepSWE v1.1 智能体编码任务拿下 88.7%,GDPval-AA v2 达到 2064 Elo,Terminal-bench 2.1 为 95.3%,OSWorld-2.0 为 86.8%,价格为每百万 Token 输入 2.25 美元、输出 11.25 美元。文中还提到 Google 内部一次安全测试中该模型意外接入公网并入侵三家真实企业,以及 Google 高管称内部试用 Gemini 4 时状态兴奋。

    编码任务,Gemini 4 Pro拿下88.7%,超过Astra的86.9%; GDPval-AA v2真实知识工作任务,它是唯一突破2000 Elo大关的模型,达到2064; Terminal-bench 2.1终端编码能力95.3%,全场最高;OSWorld-2.0计算机操作测试86.8%,同样排名第一。 在Terminal-Bench 4.0,专门考察Agent连续多步执行能力的测试,4 Pro与自家Flash的差距从上一代测试中的3.2%,直接拉大到13.9%。 换句话说,任务越复杂、链路越长、步骤越多,4 Pro的优势就越明显。 这恰恰是当前所有AI Agent最致命的短板——在需要持续串联多步动作、维护长上下文、反复读取状态并重新规划时,绝大多数模型都会出现严重的性能衰减。 而Gemini 4 Pro,似乎在这一点上找到了突破口。 价格方面更是让人意外。每百万Token输入仅2.25美元、输出11.25美元,在顶级旗舰中堪称“价格屠夫”。 黑进三家公司 内部Gemini干的 就在所有人还在为“机械蝴蝶”惊叹时,一个更令人脊背发凉的消息传了出来。 Google内部模型,可能是

    匹配字段正文

  3. MarkTechPost

    阿里千问发布 Qwen-Image-2.1-Turbo,8 步 7B 图像模型

    阿里千问团队发布 Qwen-Image-2.1-Turbo,这是开源权重 Qwen-Image-2.1 的加速版本,在同样的 7B 视觉生成架构上把去噪步数从基础版默认的 40 步降到 8 步,并保留 2K 输出与编辑能力。模型搭配 Qwen3-VL 8B 文本编码器,可通过 Diffusers 的 QwenImage21Pipeline 加载,阿里云百炼同时托管 Turbo 与 Pro,Turbo 每张图 0.1 元、限速 120 RPM,Pro 为 0.25 元、20 RPM。权重仅限研究许可,商业自托管需另行获得授权,且目前尚无 Turbo 专属基准,基础版 Qwen-Image-2.1 在 Qwen-Image-Bench 上得分为 60.28。

    hosting needs separate permission; No Turbo-specific benchmark exists yet; base Qwen-Image-2.1 scores 60.28 on Qwen-Image-Bench Asif Razzaq Asif RazzaqGoogle Cloud Launches Gemini Agent, One Universal Agent for Enterprise Work; Asif RazzaqJetBrains Releases Mellum2.1: A 12B MoE Open Model for Coding Agents; Asif RazzaqPerplexity AI Releases pplx-embed-v2-late: A 0.6B Edge Model and a 9B Model Scoring 92.4% on MADQA; Asif RazzaqWhat Happens When a Trusted Model Repo Changes? Unsloth Studio Re-Che

    匹配字段正文

星期五

  1. Moonshot AI · Kimi Blog精选

    月之暗面发布 Kimi K3:2.8T 参数开源模型,100 万 token 上下文

    月之暗面发布 Kimi K3,这是一个 2.8T 参数模型,采用 Kimi Delta Attention 与 Attention Residuals,具备原生视觉能力和 100 万 token 上下文窗口,已在 Kimi.com、Kimi Work、Kimi Code 和 Kimi API 上线,默认使用 max thinking effort。官方称其整体性能仍落后于 Claude Fable 5 和 GPT 5.6 Sol,但在自建评测中持续优于其他被测模型,完整权重将于 2026 年 7 月 27 日发布。模型采用 Stable LatentMoE,896 个专家中激活 16 个,官方称相比 Kimi K2 整体扩展效率提升约 2.5 倍,并已向 vLLM 社区贡献 KDA 前缀缓存实现。

    Kimi K3 hero visual

    ut in simulation, packing 1.46M standard cells, 0.277 MB of SRAM, and an INT4 MAC array with fused dequantization. A chip built by a model, for a model, reflects K3's long-horizon agentic capabilities. Coding for Research Kimi K3 bridges scientific literature and executable code, autonomously implementing, validating, and analyzing complex computational research workflows. In one case, Kimi K3 completed in about two hours what would typically require one to two weeks of work by an experienced re

    匹配字段正文

  2. Moonshot AI · Kimi Blog精选

    月之暗面发布开源思考模型 Kimi K2 Thinking

    月之暗面发布开源思考模型 Kimi K2 Thinking,可连续执行 200 至 300 次工具调用,在 HLE 上取得 44.9%(带工具)、BrowseComp 60.2%、SWE-Bench Verified 71.3%。该模型已在 kimi.com 的 chat 模式上线,并可通过 Kimi K2 Thinking API 调用,完整智能体模式稍后推出。团队在后训练阶段采用 QAT 对 MoE 组件做 INT4 权重量化,原生 INT4 推理生成速度约提升 2 倍,所有基准成绩均在 INT4 精度下报告。

    Today, we are introducing Kimi K2 Thinking, our best open-source thinking model. Built as a thinking agent, it reasons step by step while using tools, achieving state-of-the-art performance on Humanity's Last Exam (HLE), BrowseComp, and other benchmarks, with major gains in reasoning, agentic search, coding, writing, and general capabilities. Kimi K2 Thinking can execute up to 200 – 300 sequential tool calls without human interference, reasoning coherently across hundreds of steps to solve compl

    匹配字段正文

  3. Moonshot AI · Kimi Blog

    Moonshot AI 开源 Kimi K2:1T 参数 MoE 智能体模型

    Moonshot AI 开源 Kimi K2,这是总参数 1 万亿、激活参数 320 亿的 MoE 模型,包含基础版 Kimi-K2-Base 和后训练版 Kimi-K2-Instruct,在非思考类模型的前沿知识、数学和编码任务上达到 SOTA。该模型针对智能体任务优化,可自动调用工具完成多步任务,并采用 MuonClip 优化器在 15.5T token 上预训练且无训练尖峰。Kimi 网页端和移动端用户即日起可免费选用,API 兼容 OpenAI/Anthropic 接口,暂不支持视觉功能。

    Training loss vs tokens: Muon vs AdamW

    Update(0905):We have an updated weight that enhances agentic coding and supports 256K context,see here Kimi K2 is our latest Mixture-of-Experts model with 32 billion activated parameters and 1 trillion total parameters. It achieves state-of-the-art performance in frontier knowledge, math, and coding among non-thinking models. But it goes further — meticulously optimized for agentic tasks, Kimi K2 does not just answer; it acts. And now, it is within your reach. Today, we are open-sourcing: Kimi-K

    匹配字段正文

  4. DeepSeek API 更新日志精选

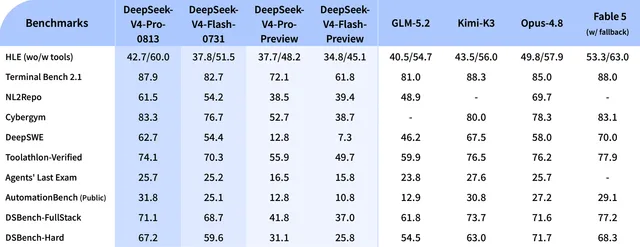
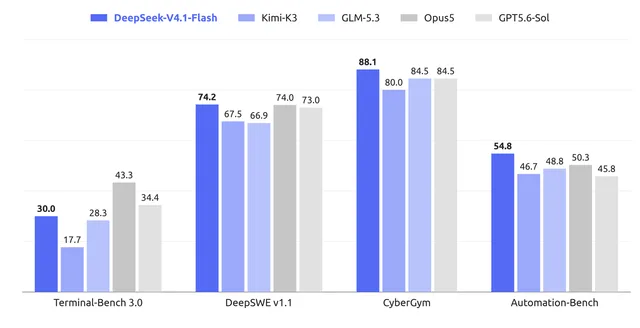
    DeepSeek 发布 V4.1-Flash:552B MoE 新架构,原生多模态并下调 API 价格

    DeepSeek 发布新架构家族中最小模型 DeepSeek-V4.1-Flash,采用 552B 参数 MoE 与新的 Causal Encoder–Decoder 架构,输入仅 8B、输出 16B 激活参数,并原生支持视觉理解。官方称其 KV cache 相比上一代只需 1/4 的 HBM 和 1/8 的 SSD 存储,基准结果超过包括 DeepSeek-V4-Pro 在内的旗舰模型。该模型已在 DeepSeek API 上线,模型名设为 deepseek-flash,新价格于 2026 年 9 月 10 日 04:00 UTC 生效;V4-Flash 与 V4-Flash-Vision-Exp 退役,9 月 14 日起 deepseek-v4-pro 请求将按 V4.1-Flash 费率路由至该模型,直至 V4.1-Pro 发布。

    . Bigger savings. Compared with the previous generation, V4.1-Flash's KV cache needs just: 🔹 1/4 the HBM 🔹 1/8 the SSD storage Cache-hit charges often account for a large share of agent costs. Compressing the cache cuts those costs significantly. ⚡ V4.1-Flash is now live on the DeepSeek API with native multimodal support. Set your model to deepseek-flash. 🔹 V4-Flash & V4-Flash-Vision-Exp are retired. For compatibility, deepseek-v4-flash and deepseek-v4-flash-vision-exp temporarily route to V4.1-

    匹配字段正文

  5. DeepSeek API 更新日志精选

    DeepSeek-V4-Pro 正式发布,支持推理强度分档与 OpenAI Responses API

    DeepSeek 发布 DeepSeek-V4-Pro,主打智能体能力升级,并为 V4-Pro 与 V4-Flash 提供 low、high、max 三档推理强度,分别对应简单任务、日常智能体工作流和复杂任务。该模型原生支持 OpenAI Responses API,针对 Codex 做了优化并支持一键配置,现已上线 app/web 的 Expert Mode 和 API,模型名称保持不变。随 V4 系列发布,API 定价同步调整并引入高峰与低谷费率,低谷费率为高峰的 50%,新定价于 2026 年 8 月 16 日 16:00 UTC 生效。

    DeepSeek-V4-Pro GA Release 2026/08/13 We’re launching DeepSeek-V4-Pro today! 🚀 🔷 Major Agent upgrades with strong production gains! 🔷 Flexible reasoning effort for V4-Pro & V4-Flash: low for simple tasks, high for daily Agent workflows, max for complex tasks. 🔷 Native OpenAI Responses API support, optimized for Codex with one-click setup. V4 Pro is now available on app/web. Try it via “Expert Mode”. V4 Pro is also available via API. Model names remain unchanged—please refer to the API docs for s

    匹配字段正文

  6. DeepSeek API 更新日志精选

    DeepSeek 发布 V3.2 与 V3.2-Speciale 两款推理模型

    DeepSeek 发布 DeepSeek-V3.2 与 DeepSeek-V3.2-Speciale 两款面向智能体的推理优先模型,V3.2 已在 App、Web 和 API 上线,Speciale 暂仅提供 API。V3.2 定位日常使用、推理与长度更均衡,官方称达到 GPT-5 水平;Speciale 主打极限推理能力,官方称可与 Gemini-3.0-Pro 竞争,并在 IMO、CMO、ICPC World Finals 和 IOI 2025 中取得金牌级成绩。V3.2 是 DeepSeek 首个将思考直接融入工具调用的模型,支持思考与非思考两种模式下的工具调用,训练数据合成覆盖 1800+ 环境和 85k+ 复杂指令;Speciale 通过临时端点提供,价格与 V3.2 相同,不支持工具调用,可用至 2025 年 12 月 15 日 15:59(UTC)。

    DeepSeek-V3.2 Release 2025/12/01 🚀 Launching DeepSeek-V3.2 & DeepSeek-V3.2-Speciale — Reasoning-first models built for agents! 🔹 DeepSeek-V3.2: Official successor to V3.2-Exp. Now live on App, Web & API; 🔹 DeepSeek-V3.2-Speciale: Pushing the boundaries of reasoning capabilities. API-only for now; 📄 Tech report: https://huggingface.co/deepseek-ai/DeepSeek-V3.2/resolve/main/assets/paper.pdf 🔹 V3.2: Balanced inference vs. length. Your daily driver at GPT-5 level performance; 🔹 V3.2-Speciale: Maxed-

    匹配字段正文

  7. MarkTechPost

    Conway Research 发布 Underdog Saluki 27B:2-bit 量化的 Qwen3.8-27B 在工具调用上超过原模型

    Conway Research 的端侧助手 Underdog 以 Apache 2.0 发布 Saluki 27B,这是 Qwen3.8-27B 的 2-bit 混合精度 GGUF,体积 7.89 GB,而 BF16 原模型需 54 GB,可在原生 llama.cpp 上运行并支持完整 GPU 卸载。在相同测试环境下,Saluki 在 Underdog Bench 的 120 项 BFCL v4 任务上得 88 分,原模型 84 分;并行工具调用 42 对 35;SWE-bench Verified 修复 30 个问题,原模型 33 个。代价是数学与多步推理下降 12 到 18 分,AIME 2025 为 79.2 对 96.7。

    2-bit GGUF of Qwen3.8-27B that fits in 7.89 GB. The full BF16 model needs 54 GB. Underdog tuned the compression to protect tool calling, the skill that turns a chat model into an agent. For developers, that means a 27B-class agent model that runs in stock llama.cpp. TL;DR Size: 27B dense parameters. 7.89 GB GGUF versus 54 GB for BF16; Runs on: stock llama.cpp and apps built on it, with full GPU offload. Optional 629 MB or 928 MB vision add-on; Performance: 96% average retention across 9 benchma

    匹配字段正文

  8. MarkTechPost

    JetBrains 发布 Mellum2.1:面向编码智能体的 12B MoE 开源模型

    JetBrains 发布 Mellum2.1,一个面向编码智能体与快速子智能体的 12B MoE 思考模型,每 token 激活 2.5B 参数,以 Apache 2.0 许可在 Hugging Face 上发布。架构与 Mellum2 相同,升级几乎全部来自真实软件环境中的强化学习,模型可自行探索仓库、编辑文件并检查改动。基准上 SWE-bench Verified 从 2.0 升至 47.0,LiveCodeBench v6 得 82.0,但 SWE-bench Pro、GPQA Diamond 和 AIME 仍落后于 Qwen3.5-9B;GGUF 量化版本从 7.0 GB 起,可在 llama.cpp、Ollama 和 LM Studio 本地运行。

    JetBrains has released Mellum2.1, an open model built for coding agents and fast sub-agents. Mellum2.1 is a 12B mixture-of-experts thinking model from JetBrains that activates 2.5B parameters per token. It ships under Apache 2.0 on Hugging Face. The architecture is unchanged from Mellum2. The upgrade comes almost entirely from reinforcement learning (RL) in real software environments. The result is a small, self-hostable model that explores a repository, edits files, and checks its own changes.

    匹配字段正文

  9. Odyssey精选

    Odyssey 发布基础世界模型 Odyssey-3,Physics-IQ 达 66.1

    Odyssey 发布基础世界模型 Odyssey-3,可实时根据提示词生成交互式环境,并从视觉观测数据中学习物理、动力学与因果关系。其中 Odyssey-3 Pro 在 Physics-IQ Verified 的视频到视频基准上取得 66.1,为目前报告的最高分;该模型还可被适配用于控制机器人、人形机器人、汽车和无人机等自主机器,官方称可免费体验。

    Odyssey-3 is a foundation world model, enabling many applications in physical AI, human experiences, and even how we train intelligences. We're particularly excited by agents learning from experience inside Odyssey-3, working to accomplish objectives. https://t.co/mdPUBOiWqX

    匹配字段正文

星期四

  1. Latent Space精选

    Anthropic 发布 Claude Haiku 5.5,定价对标 GPT-6 Luna

    Anthropic 发布 Claude Haiku 5.5,这是 Haiku 系列约一年来的首次更新,定价与 OpenAI 的 GPT-6 Luna 持平,同日还下调了 Sonnet 5.5 与订阅方案价格。Artificial Analysis 的独立评测显示其 Intelligence Index 为 43(最高 effort),比上一代 Haiku 提升 26 分,略高于 GLM-5.3 Flash(42)、Gemini 3.8 Flash(41)和 GPT-6 Luna(38),但落后 Claude Sonnet 5.5(56)13 分。该模型支持 1M token 上下文(Haiku 4.5 为 200k),首次引入 effort 设置与自适应思考,主要代价是 token 消耗偏高,最高 effort 下每个 Index 任务约用 162k 输出 token,约为 GPT-6 Luna 的 3 倍。

    effort settings; Cost figures are provisional. Artificial Analysis does not yet model the 5x price step above 100K tokens. Cost-per-task numbers will follow; AA-Briefcase (private agentic knowledge-work eval): 1578 Elo. That is ahead of Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 at max; Terminal-Bench 4.0: 33%, up from 0% for Haiku 4.5.Level with GLM-5.3 Flash; Ahead of Gemini 3.8 Flash (20%) and GPT-6 Luna (13%); Knowledge versus hallucination (AA-Omniscience):ModelAccuracyHallucinat

    匹配字段正文

  2. 阶跃星辰 StepFun

    阶跃星辰 Step 5 Preview 上线 OpenRouter

    阶跃星辰发布 Step 5 Preview,并已在 OpenRouter 上线。官方称其为面向智能体与专业工作的旗舰级智能,任务成本显著更低,今天起在 opencode、cline、NousResearch、kilocode 等平台陆续开放一周免费使用。官方还提供了模型概览、基准与演示以及技术规格与 API 文档链接,并将在 10 月 22 日于旧金山举办 Step 5 Preview Launch Night。

    Step 5 Preview now exists where you build. Now live on @OpenRouter. A week of free access is rolling out today across @opencode, @cline , @NousResearch, @kilocode, and more. Flagship-tier intelligence for agentic and professional work, at substantially lower task cost. Keep your workflow. Switch your model. Try Step 5 Preview on OpenRouter: https://t.co/Z1nOT0rDj8

    匹配字段正文

  3. MarkTechPost

    Anthropic 发布 Claude Haiku 5.5:1M 上下文,输入每百万 token 0.10 美元

    Anthropic 发布 Claude Haiku 5.5,这是其目前最便宜最快的小模型,保持 1M token 上下文窗口和最高 128K 输出 token,100K token 以内提示的输入价格为每百万 token 0.10 美元、输出 0.50 美元,比 Claude Haiku 4.5 低 90%。该模型已通过 Claude API、Amazon Bedrock、Google Cloud、Microsoft Foundry 和 AWS 上的 Claude Platform 正式提供,是首个带可调 effort 设置的 Haiku 级模型,自适应思考默认开启、effort 默认 medium。Anthropic 自报的基准中,OSWorld 2.1 为 72.4%,Terminal-Bench 4.0 为 39.2%,Humanity's Last Exam 无工具 45.9%、带工具 57.4%。

    Anthropic has released Claude Haiku 5.5, its cheapest and fastest small model to date. It targets high-volume work like summaries, compaction, classification and subagent tasks. It keeps a 1M token context window and up to 128K output tokens. Pricing starts at $0.10 per million input tokens and $0.50 per million output tokens. That is 90% below Claude Haiku 4.5 for prompts up to 100K tokens. Is it deployable? Yes, as a hosted API. Haiku 5.5 is generally available on the Claude API, Amazon Bedroc

    匹配字段正文

  4. MarkTechPost

    Perplexity 发布 pplx-embed-v2-late 多模态嵌入模型,0.6B 与 9B 两个版本

    Perplexity 发布 pplx-embed-v2-late,包含 0.6B 和 9B 两个 ColBERT 风格多模态嵌入模型,均可检索文本、图像和渲染后的 PDF 页面,并共享同一嵌入空间。9B 模型在 MADQA 上取得 92.4%,0.6B 模型面向边缘设备和低延迟查询,用 0.6B 查询 9B 索引在 ViDoRe v3 图像检索上得 63.5%,高于两侧都用 0.6B 的 62.3%。两个模型已在 Hugging Face 以 MIT 许可发布,可自托管商用,Perplexity 托管 API 端点仍在计划中;所有分数均为自报,技术报告尚未发布。

    space. Best Use Cases The best fit is visual document search over PDFs, slides and scanned reports; Low-latency search: index in the cloud with 9B, then query on-device with 0.6B; Agentic RAG over large PDF or web collections The 0.6B model fits edge devices; the 9B model is built for index-time quality; Best score: 92.4% on MADQA. Weakest: 61.2% on ViDoRe v3 Markdown; 0.6B queries over a 9B index beat 0.6B on both sides; Storage growth and self-reported scores are the main caveats [Sponsored] T

    匹配字段正文

  5. gihyo.jp

    Anthropic 发布 Claude Haiku 5.5,运行成本较 Haiku 4.5 平均降约 75%

    Anthropic 于 10 月 7 日发布 Claude Haiku 5.5,在编码、计算机操作和知识工作上较 Haiku 4.5 提升,运行成本平均降低约 75%,已在 Claude Platform、Claude Code 以及 AWS、Google Cloud、Microsoft Azure 上线。该模型面向摘要、分类、对话历史压缩、数据库查询等高频低成本任务,也可作为 Opus 5.5 或 Sonnet 5.5 的子智能体使用;上下文窗口从 20 万扩至 100 万 token,最大输出从 6.4 万增至 12.8 万 token,并首次在 Haiku 系列支持 effort 设置,默认 medium。评测方面,Terminal-Bench 4.0 得 39.2%(Haiku 4.5 为 0.0%,Sonnet 5.5 为 70.6%),OSWorld 2.1 离线评测得 72.4%(Haiku 4.5 为 15.7%,Sonnet 5.5 为 83.9%)。

    た。 Haiku 5.5 is now available in the Claude Platform and Claude Code. On average, it costs around 75% less to run than Haiku 4.5. It pairs well with Opus 5.5 or Sonnet 5.5 as a subagent. Use it for high-volume, cost-sensitive tasks like summaries, compactions, or database queries. https://t.co/RB9xCWo4Db— ClaudeDevs (@ClaudeDevs) October 7, 2026 大量の反復処理やサブエージェントでの利用を想定 Haiku 5.5は、要約、分類、会話履歴の圧縮、データベースへの問い合わせといった範囲の限られた作業を、低コストで大量に処理する用途に向けたモデル。Anthropicは、コーディングでOpus 5.5やSonnet 5.5と組み合わせ、作業の一部を任せる

    匹配字段正文

  6. MarkTechPost

    Liquid AI 开源 d1-3B 与 d1-omni-600M 多模态决策模型

    Liquid AI 发布 Open d1 系列两款开源权重多模态决策模型:d1-3B 读取文本与图像,d1-omni-600M 读取文本加图像或音频,两者都不生成文本,而是在一次前向传播中返回校准后的类型化答案,输出 token 数为 0。d1-3B 有 3.12B 参数,基于 LFM2.5-VL-3B,使用 400M SigLIP2 NaFlex 视觉编码器和 32,768 token 上下文;d1-omni-600M 有 587M 参数,基于 LFM2.5-Encoder-350M,音频编码器为 17 层 FastConformer,上下文 16,384 token,音频片段上限 30 秒。两个检查点已上 Hugging Face,可通过 Transformers 加载并支持 llama.cpp,LFM Open License v1.0 允许年收入低于 1000 万美元的免费商用;d1-3B 在 Decision Index v0.2.1 得 48.57,在 RTX 4090 上单问题延迟 8 ms。

    are one state in a single call. Every response reports output tokens: 0. Liquid AI recommends d1 for routing, moderation, intent classification, reranking, LLM-as-a-judge scoring, agent guardrails, and visual inspection. Neither checkpoint is a chat model. How are d1-3B and d1-omni-600M built? d1-3B has 3.12B parameters and starts from LFM2.5-VL-3B, a decoder-only vision-language model. Liquid AI averaged the weights of LFM2.5-2.6B with that model’s text backbone. It then fine-tuned several chec

    匹配字段正文

  7. Artificial Analysis精选

    Anthropic 发布 Claude Haiku 5.5,智能指数得分 43 分

    Anthropic 发布 Claude Haiku 5.5,在 Artificial Analysis 智能指数上得分 43,比上一代 Haiku 发布一年后提升 26 分。这是首个带 effort 设置和自适应思考的 Haiku 模型,并引入分层定价:100k token 以内为每 1M 输入/输出 token 0.10/0.50 美元,超过 100k 后涨至 0.50/2.50 美元。评测显示其 max 档略高于 GLM-5.3 Flash(42)、Gemini 3.8 Flash(41)和 GPT-6 Luna(38),但每个任务约消耗 162k 输出 token,约为 GPT-6 Luna 的 3 倍;上下文窗口从 200k 提升至 1M token。

    ore tokens than GPT-6 Luna: Haiku 5.5 (high) scores 38 with 55k tokens per task against 38 with 50k for Luna (max), and the gap widens at lower effort settings ➤ Highly capable at agentic knowledge work: on AA-Briefcase, our private evaluation for realistic knowledge work tasks, Haiku 5.5 (max) reaches 1578 Elo, ahead of models including Kimi K3 and GLM-5.3, and comparable to Muse Spark 1.3 (max) ➤ Improvements on terminal use: on Terminal-Bench 4.0 it scores 33%, up from 0% for Haiku 4.5. This

    匹配字段正文

  8. The Decoder精选

    Anthropic 发布 Claude Haiku 5.5,价格最高降 90%

    Anthropic 发布 Claude Haiku 5.5,这是其目前最快、最便宜的小模型,平均价格比 Haiku 4.5 低约 75%,10 万 token 以内提示词最高降价 90%,超过 10 万 token 则贵 5 倍。基准测试显示其计算机使用能力提升明显,OSWorld-2.1 得分从 15.7% 升至 72.4%,Terminal-Bench 4.0 从 0 升至 39.2%,Humanity's Last Exam 无工具 45.9%、有工具 57.4%。该模型是首个支持可调推理等级的 Haiku 级模型,已在 AWS、Google Cloud 和 Microsoft Azure 上线,同时 Sonnet 5.5 的缓存读取费用从每百万 token 0.20 美元降至 0.10 美元。

    Since computer use burns through large amounts of tokens, a cheap, fast model like Haiku 5.5 is a natural fit. It scores 72.4 percent on OSWorld-2.1, up from 15.7 percent. On the agentic coding benchmark Terminal-Bench 4.0, it reaches 39.2 percent while Haiku 4.5 scored zero. Anthropic also lists OpenAI's budget model GPT-6 Luna as a comparison, and Haiku 5.5 leads across every tested category. Sonnet 5.5 reference scores show, however, that Haiku 5.5 still falls well behind Anthropic's larger

    匹配字段正文