←搜索结果

按匹配度 · 共 1155 条结果 清除搜索

星期三

  1. MarkTechPost精选

    OpenAI 在 DevDay 发布 dots:基于 GPT-6 Astra 的常驻智能体

    OpenAI 在 DevDay 发布 dots,这是由 GPT-6 Astra 驱动的常驻智能体,每个 dot 拥有自己的云计算机和浏览器,可通过 ChatGPT 插件跨 4000+ 应用工作,用户登出后仍继续运行。dots 以托管产品形式在 ChatGPT 的 Pro 和 Business Premium 用户中于符合条件市场推出,Enterprise、Edu 和 Healthcare 工作区需管理员开启后进入 beta,不提供自托管或开放权重版本。OpenAI 的延迟模拟显示,GPT-6 Astra 在 OSWorld 2.0 上得分 72.6%,每任务约 40 分钟,GPT-5.6 Sol 为 65.7%、约 75 分钟;OpenAI 同时预览了面向固定角色的 specialist dots,并称 dots 仍可能出错,重要工作需人工复核。

    OpenAI just introduced dots at their DevDay today. Dots are persistent AI agents powered by GPT-6 Astra . Each dot gets its own cloud computer and browser. It works across 4,000+ apps through ChatGPT plugins and keeps going after you log off. Is it deployable today? Yes, as a managed product. Dots are rolling out in ChatGPT for Pro and Business Premium users in eligible markets. Enterprise, Edu and Healthcare workspaces get a beta once an admin turns it on. There is no self-hosted or open-weight

    匹配字段正文
  2. Wired AI

    OpenAI 发布常驻智能体 Dots,由 GPT-6 Astra 驱动

    OpenAI 发布常驻型 AI 智能体 Dots,由 GPT-6 Astra 模型驱动,可持续爬取网页并尝试完成用户指派的任务,还能从已连接应用获取上下文、逐步学习用户偏好。用户可通过 ChatGPT、Slack 和 Microsoft Teams 与 Dots 交互,Pro 用户可加入等待名单在 iMessage 或 Android 的 RCS 中与 Dots 发消息。OpenAI 同时在 DevDay 上宣布面向企业客户的 specialist Dots,针对会计、邮件营销和法律分析等特定任务调优;Dots 在执行安装软件或修改密码等敏感操作前会请求明确批准,并提供 Custom Rules 工具设定边界。

    OpenAI’s Dots are powered by the startup’s GPT-6 Astra model . A core selling point is their “always-on” design—unlike a single-turn chatbot experience, these agents constantly crawl the web and attempt to complete whatever task you assign to them. Dots also pull context from connected apps and learn more about your preferences over time. In one demo example shared by OpenAI, a user’s Dot helps plan dinner. The Dot proactively saw that the user’s calendar showed they were working through dinner

    匹配字段正文

星期二

  1. Meta:Newsroom · AI

    Meta 为 Muse 推出小企业版,接入 Asana、Shopify、Stripe 等工具

    Meta 宣布推出 Muse for Small Business,为 Muse 增加一批面向小企业经营的新技能和连接器。用户可连接 Asana、Box、Canva、Dropbox、Figma、Granola、HighLevel、Intuit QuickBooks、Klaviyo、Lovable、Notion、Shopify、Slack、Stripe、Zoom 以及 Facebook 和 Instagram 商业账号,Muse 会据此了解业务情况。官方称任何发布、发送或支出操作都需用户批准,Muse 对多数需求免费,更多功能需订阅,并支持自定义连接器。

    designed and how safety, security, and privacy were built into it, read How We Built Safety Into Muse and How We Designed Muse Earlier this month we introduced Muse, a personal AI agent available in the US and Canada that completes tasks on your behalf. Today, we’re expanding it with a collection of new skills and connectors inside Muse to help people run their businesses. Small businesses have been growing on our apps for nearly two decades. They told us they’re short on hours, not ideas. So we

    匹配字段正文

  2. Inception Labs Blog

    Inception 发布 Mercury 2,面向搜索流水线每步延迟最快

    Inception Labs 发布 Mercury 2,称其在标准 NVIDIA GPU 上解码速度超过 1000 tokens/秒,在 WideSearch 基准的搜索流水线每一步都最快,查询规划比 Gemini 3.1 Flash Lite 快近 2 倍、比 Claude Haiku 4.5 快 4.7 倍、比 GPT-5 Mini 快 10 倍。定价为 $0.25/M 输入、$0.75/M 输出,作者称更深的流水线运行成本约为前沿速度优化模型的 2 倍便宜。在 FRAMES 上四款模型得分接近,DeepSearchQA 上 GPT-5 Mini 以 0.44 高于 Mercury 2 的 0.34,但 Mercury 2 完成 FRAMES 查询耗时 10.8 秒、单次正确回答成本最低。作者还发现 WideSearch 任务可被模型凭记忆作答,重建为训练截止后事件的任务后,Gemini 得 0.929、Mercury 2 得 0.923。API 已在 platform.inceptionlabs.ai 上线。

    For the past two years, “search” stopped meaning a ranked list of links and started meaning an agentic pipeline. Classify, rewrite, fan out, rerank, and synthesize. Fifty to a hundred LLM calls per search query, almost all sequential. That's a brutal place to put an autoregressive model: a 400ms rewrite blocks retrieval, which blocks reranking, which blocks the first word the user sees. So teams cut the pipeline down until it's shallow enough to be fast. The industry has split into two camps: sy

    匹配字段正文

  3. Inception Labs Blog精选

    Inception 的 Mercury 扩散 LLM 上线 Azure AI Foundry

    Inception 宣布 Mercury 扩散大语言模型在 Azure AI Foundry 上线,面向企业开发者提供商用规模的 dLLM。该模型通过扩散架构并行生成多个 token,推理速度最高可达同类自回归模型的 10 倍,在知识、编码、指令遵循和数学基准上与 Gemini 2.5 Flash、Claude 4.5 Haiku 相当。它支持 128K token 上下文窗口、原生工具调用和 JSON schema 结构化输出,API 兼容 OpenAI,目前在美国和加拿大区域提供,软件许可费用为 $0.78/小时,计算费用另计。

    token context window for processing large documents and maintaining extensive conversations, with native tool calling and structured output support using JSON schemas for building agentic workflows. The API is OpenAI-compatible, making integration with existing codebases seamless. Azure AI Foundry provides enterprise-grade infrastructure, including network isolation, data privacy guarantees ensuring your data stays in your Azure environment and is never used for training, Azure compliance standa

    匹配字段正文

  4. Inception Labs Blog

    Inception Labs 更新 Mercury 系列扩散 LLM 产品线

    Inception Labs 在其产品博客集中列出 Mercury 系列扩散 LLM 的进展:Mercury 2 面向搜索场景,可在既有延迟预算内为每次查询执行五十到一百次 LLM 调用;Mercury 2 用于语音智能体时 TTFT 低于 300 ms,并已上线 Azure AI Foundry。Mercury 2.5 被称为市面上能力最强的扩散 LLM,运行速度 1,107 tokens/sec,智能水平较 Mercury 2 提升 40%。此外,Mercury 2 新 API key 可获 100M 免费 tokens,速率限制提升 10 倍。

    Mercury 2 for Search: Fast enough to run a hundred times per query Mercury Voice is a diffusion LLM (dLLM) tuned to power voice agents. It reasons, calls tools, and follows long system prompts while keeping latency low enough for natural conversation. Mercury 2.5 is the most capable diffusion LLM on the market. It runs at 1,107 tokens/sec and offers a 40% increase in intelligence over Mercury 2, comparable to cost-optimized frontier models. Sep 8, 2026 Product Mercury 2 for Search: Fast enough t

    匹配字段正文

  5. AWS Machine Learning

    xAI 的 Grok 4.7 上线 Amazon Bedrock

    xAI 的 Grok 4.7 已在 Amazon Bedrock 上线,支持 500K token 上下文窗口和 low、medium、high、xhigh 四档可配置推理强度,通过 bedrock-runtime 的跨区域推理配置文件提供服务,支持 Responses、Chat Completions 和 Converse API。xAI 称这是其编码与知识工作能力最强的模型,训练中加大了长耗时任务的强化学习比重,因此更擅长自我校验并更有效利用长上下文。Artificial Analysis 的独立评测显示其在长周期智能体知识工作和编码智能体上提升最大,但每任务输出 token 约为原来的两倍。

    xAI’s Grok 4.7 is now available on Amazon Bedrock, adding a frontier model built for coding, long-running agents, and knowledge work to the Bedrock model catalog. It offers a 500K token context window and supports configurable reasoning effort at four levels: low, medium, high, and xhigh. Grok 4.7 is served on the bedrock-runtime endpoint through cross-Region inference profiles, and it supports the Responses, Chat Completions, and Converse APIs. According to xAI, it’s their most capable model fo

    匹配字段正文

星期一

  1. NVIDIA Developer · Generative AI

    NVIDIA 发布 OpenShell 0.1.0,为 AI 智能体加上运行时权限控制

    NVIDIA 发布开源运行时 OpenShell 0.1.0,可在不重写智能体的前提下限制其可访问的系统与数据,结合沙箱执行、受控服务访问、凭证管理和形式化策略分析。OpenShell 由 Gateway、Supervisor 和 Sandbox 组件管理智能体集群,可检查 HTTP、GraphQL 和 MCP 流量,允许同一 API 上的读操作而拦截写操作,并将策略决策记录到 OCSF 审计日志。Cadence、Slack 和 Gecko Robotics 等组织已在芯片设计、企业自动化和物理机器人治理中采用该运行时。

    rch.text-copy'); sessionStorage.removeItem('facets.search.filters'); Sep 28, 2026 NVIDIA OpenShell 0.1.0 provides an open-source runtime that enforces which systems and data an AI agent can access without rewriting the agent. The runtime combines sandboxed execution, controlled service access, credential management, and formal policy analysis to restrict API operations and protect credentials outside the agent workload. Organizations including Cadence, Slack, and Gecko Robotics are adopting Open

    匹配字段正文

  2. Hugging Face

    Hugging Face 在 Hub 上线 RL Environments 功能

    Hugging Face 在 Hub 上线 RL Environments,用 rl-environment 标签把环境作为数据集托管,并注册 Harbor、Verifiers、OpenEnv、NeMo Gym 四个框架标签,数据集页面会显示框架图标并生成加载命令。用户可在 datasets?other=rl-environment 筛选查看,文中给出了各框架运行任务并检查 verifier 奖励的示例命令。官方已为 BeyondSWE、Terminal-Lego、Multi-SWE-RL-Verified、Workplace Assistant 等已有环境提交打标签的 PR,后续计划支持按配置生成片段和自动打标签。

    nd run it in a separate Python environment with the prerequisites listed below. Harbor: run a reference solution Harbor can load task directories from a Hub repository. The oracle agent runs the task's reference solution, then the verifier scores the result. It does not call a model. The viewer shows the task's reward, verifier output, and logs. This checks the task and its reference solution before you try a model agent. Verifiers: run a model on the same task The Harbor integration of verifier

    匹配字段正文

  3. Anthropic:Claude.dev 开发者博客

    Anthropic 为 claude-api 技能加入 build-eval 与 hillclimb 命令

    Anthropic 在 claude-api 技能中新增 /claude-api build-eval 和 /claude-api hillclimb 两条命令,前者在代码库内构建评测集并校验评分器,后者按单次改动迭代提升应用表现,并用留出集检测过拟合。文章给出评测设计原则,包括任务贴近生产、前沿模型留有提升空间、低运行间方差,以及用人工判断的难题而非模型当前失败案例来采样。示例中,客服工单基准从 Opus 4.8 默认高 effort 的 74.4% 准确率、每单 4.6 美分,经提示词审计与换用 Opus 5.5 低 effort 后降到 1.9 美分,最终 Sonnet 5 配置在 14 条留出工单上达到 90.5%,成本约为原来的五分之一。

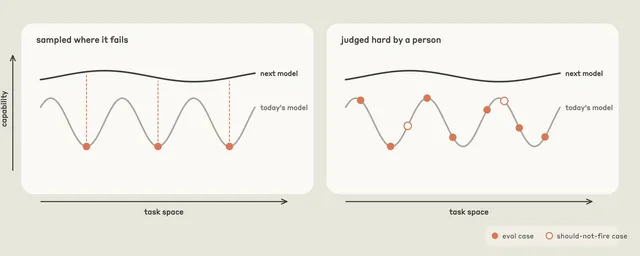
    Two panels plotting capability across task space, each with today’s model as a jagged curve and the next model as a smoother curve above it. On the left, cases sampled where today’s model fails sit only in its valleys; on the right, cases a person judged hard are spread across peaks and valleys, with a few should-not-fire cases.

    , effort may not be applied consistently. Also, the environment can affect the results of the evaluation: leftover state from an earlier trial (a file, a git history) can hand the agent the answer Adversarial sampling Model capability is jagged. If you pick cases because today's model fails them, you are sampling the valleys of one model's capability surface (Figure 2). The evaluation can end up measuring that model's failure fingerprint rather than what is intrinsically hard or valuable for you

    匹配字段正文

  4. Google Blog

    Google 发布 Gemini 3.8 Flash,展示四个开发者用例

    Google 发布 Gemini 3.8 Flash,称其在软件工程、智能体任务和跨多步推理上较 3.7 Flash 有明显提升,性能接近成本更高的前沿模型。官方称提升来自设计取向上的更肯下功夫,即在复杂任务中执行更多推理步骤并迭代调用工具。文中展示了四个用例,包括用 Google Antigravity 绘制卫星与空间站实时轨道、把青海波图案转成动态水墨画、生成霸王龙骨架,以及构建自动变速箱交互模型,用户可在 Google AI Studio 等工具中试用。

    try it out yourself in Google’s AI tools. Gemini 3.8 Flash is our most intelligent workhorse model, delivering significant improvements from 3.7 Flash across software engineering, agentic tasks, and critical, multistep reasoning in specialized domains. These performance gains stem from a core design choice: 3.8 Flash works harder. On complex tasks, it exhibits greater diligence — executing extra reasoning steps and calling tools iteratively to land a more accurate output. Builders have been crea

    匹配字段正文

  5. A6 a6-052 · Fireworks AI精选

    Fireworks AI 推出 FireRouter with Opus 路由模型

    Fireworks AI 发布 FireRouter with Opus,这是其首个缓存感知路由器,已在 CLI 上线并首次以独立路由模型形式提供,任何 Fireworks 账号都可将其作为 serverless endpoint 调用。该路由器在 Claude Opus 5.5、GLM 5.3 和 GLM 5.3 Flash 之间按任务适配度、模型成本与缓存命中损失进行路由。经过一个多月内部 A/B 测试,编码任务准确率为单独使用 Opus 的 98.1%,每次会话成本从 15.36 美元降至 6.63 美元,降幅 57%(±19 ppts),缓存命中率为 94.2%,单独使用 Opus 时为 97.8%。

    s or to an Opus-only control group, across the same workloads and users. Cost per session fell 57% (±19 ppts), from $15.36 to $6.63. To score the accuracy, we verified whether the agent finished the work, whether the right answer was reached, and whether the user had to make any corrections on the next turn. FireRouter with Opus scored 78.7% of graded turns against 80.2% for Opus-only, or 98.1% of its overall accuracy. Most of our traffic came from internal coding work, where open models could h

    匹配字段正文

  6. Fireworks AI

    Fireworks AI 推出 FireRouter with Opus 路由模型

    Fireworks AI 发布 FireRouter with Opus,这是首个缓存感知路由器,已在 CLI 上线,并首次作为独立路由模型提供,任何 Fireworks 账号都可将其作为 serverless 端点调用。该路由器在 Claude Opus 5.5、GLM 5.3 和 GLM 5.3 Flash 之间按任务适配度、提示词缓存成本和切换代价选择模型。内部一个多月的 A/B 测试显示,编码任务每次会话成本从 15.36 美元降至 6.63 美元,降幅 57%(±19 个百分点),准确率为纯 Opus 的 98.1%,缓存命中率 94.2%,纯 Opus 为 97.8%。

    s or to an Opus-only control group, across the same workloads and users. Cost per session fell 57% (±19 ppts), from $15.36 to $6.63. To score the accuracy, we verified whether the agent finished the work, whether the right answer was reached, and whether the user had to make any corrections on the next turn. FireRouter with Opus scored 78.7% of graded turns against 80.2% for Opus-only, or 98.1% of its overall accuracy. Most of our traffic came from internal coding work, where open models could h

    匹配字段正文

  7. MarkTechPost

    TypeSafe AI 发布 System One 模型 Jev 的 20 个智能体用例

    TypeSafe AI 上周发布首个 System One 模型 Jev,它不做对话、写代码或摘要,而是接收非结构化状态并返回带校准概率的类型化决策,适合智能体循环中的小判断,例如调用哪个模型、命令是否安全、哪段内容相关、智能体是否已完成。每次调用发送状态加一组类型化问题,所有问题在同一请求中并行评估,Choice 最多支持 255 个选项,并用 RLCD 训练使置信度与准确率挂钩。官方称其比逐 token 的 LLM 快 193.6 倍、便宜 444.6 倍,该数据来自 TypeSafe 自身工作流评测;OpenRouter 的 Banking77 测试中,Jev 准确率比 Claude Opus 5 低 3.3 个百分点,中位速度快 13 倍,成本约为其 1/22。

    ode or summarize. It takes unstructured state and returns typed decisions with calibrated probabilities. That makes it a natural fit for the thousands of small judgments inside an agent loop: which model to call, whether a command is safe, which passage is relevant, whether the agent is actually done. Every call sends a state (text or JSON) plus a dictionary of typed questions. TypeSafe’s docs define 3 primitives: All questions are evaluated in parallel against the same state in one request. Typ

    匹配字段正文

  8. TechCrunch AI

    Shopify 向浏览器端 AI 智能体开放结账

    Shopify 宣布面向所有符合条件的商家开放结账环节的 WebMCP 支持,浏览器端 AI 智能体不再只能搜索商品和加购,还能读取并修改结账页面、在买家授权后提交订单。该更新引入 get_checkout、update_checkout 和 complete_checkout 三个工具,可查看结账信息、修改地址或配送选项并下单,无需依赖截图或抓取网页。Shopify 此前已提供托管 MCP 服务器,此次新增的 WebMCP 面向买家浏览器内的智能体,两者都基于其 Universal Commerce Protocol(UCP)。

    While some retailers, like Amazon (and Adidas , apparently!), are blocking AI agents from making purchases on users’ behalf on their respective platforms, e-commerce platform Shopify has moved in the other direction. On Monday, the company announced that browser-based AI agents can now complete purchases on Shopify merchants’ sites, extending their capabilities beyond just searching for products and adding items to carts. Shopify previously supported WebMCP for its storefronts and carts, allowin

    匹配字段正文

星期日

  1. 量子位

    费米宇宙推出全链路量子增强大模型 FermiQLLM 1.0

    费米宇宙推出全球首个全链路量子增强大模型 FermiQLLM 1.0,基于 Qwen 开源基座模型改造,不依赖容错量子计算机,可在现有 GPU 基础设施上训练和部署。内测显示,对标同等参数量级传统大模型,其推理性能提升超过 15%,持续强化学习环节训练成本下降 25% 以上;在 MATH-500、GPQA-Diamond、BBH 等基准上综合性能提升 10%~20%。该公司成立于今年 5 月,种子轮累计融资 1 亿元,投后估值约 10 亿元,近一半员工有清华背景。

    托量子物理有望拓展现有人工智能的能力边界,为通用人工智能的发展探索新的技术路线。 △ 图源清华大学官网 在姚宏看来,Q4AI目前正处于产业发展的早期阶段。研究院相关量子研究团队与费米宇宙合作的产业级技术成果,是人工智能领域里具备重要意义的产学研有机结合的实践,期望对下一代人工智能的发展产生深刻影响。 量子怎么进入大模型? 一类更依赖量子硬件,比如让大模型充当Agent,再去调用量子计算设备完成特定优化任务。 费米宇宙走的是第二条路。 眼下,所谓的「Quantum for AI」,很多工作仍然发生在「量子启发」层面。 费米宇宙方面告诉量子位,海外已出现了一批玩家。 比如SandboxAQ,主要布局后量子密码和量子启发优化;微软Azure Quantum Elements更偏向AI4S和科学仿真;Xanadu则提供量子机器学习科研框架。 国内的企业则两条路并行,技术路线远未收敛。 作为一家基础大模型企业,传统大模型厂商所面向的各类客户均属于费米宇宙的目标客群。与此同时,传统大模型企业也是其服务对象。 接下来6到12个月,费米宇宙计划把现在针对单一基座模型的量子增强能力,进一步抽象成一套通用

    匹配字段正文

星期六

  1. gihyo.jp

    微软发布 Copilot 大型更新,推出 Home、Code 与 Autopilot

    微软 9 月 25 日宣布 Copilot 大型更新,以整合 Chat 与 Cowork 的 Home、用自然语言生成应用的 Code、以及持续执行任务的 AI 智能体 Autopilot 为三大支柱,并支持在 Copilot 内创建和编辑 Word、Excel、PowerPoint 文件。Home 与 Code 将在未来数周通过 Frontier 计划逐步开放,Autopilot 于 9 月底扩大私有预览;Cowork、Code、Autopilot 及部分高性能模型按 Copilot Credits 计量采用按量计费,企业需由管理员设定支出上限后才开始计费。Teams 中 @Copilot 调用、Today 优先事项提示以及 Fabric IQ、Work IQ 数据连接也在同步推进。

    ery model, every form factor, and every task. Today, we’re announcing our biggest update to Copilot to date, bringing four things together: · Autopilot: proactive and long-running agent built for the enterprise · Code:… pic.twitter.com/W2ClHHkCK3— Satya Nadella (@satyanadella) September 25, 2026 HomeとCodeは、一般提供前のAI機能を試せるFrontierプログラムで今後数週間に順次展開する。Autopilotは9月末にプライベートプレビューの対象を拡大する予定。機能の利用に応じた従量課金と、企業が利用額を管理する仕組みも案内した。 HomeにChatとCoworkを集約⁠、Copilot内でOffice文書の作成⁠・編集も Homeは、Copilotで作業を始めたり、途中の仕事を再開した

    匹配字段正文

  2. OpenClaw

    Microsoft 发布基于 OpenClaw 构建的常驻智能体 Autopilot

    Microsoft 发布 Autopilot,一个基于 OpenClaw 构建的常驻智能体。OpenClaw 表示这次合作中最值得关注的是 Microsoft 的 Omar Shahine 及其团队向 OpenClaw 回馈了大量贡献,相关细节可通过文中链接查看。

    Today Microsoft announced Autopilot, an always on agent built on OpenClaw The best part of this collaboration is how much @OmarShahine and others at Microsoft have contributed BACK to OpenClaw Read all about the contributions Omar and his team made here: https://t.co/JOXd6sswZ2

    匹配字段正文

  3. 量子位

    Simate 发布首版通用物理快系统 Simate-beta,登顶 RoboDojo

    成立三个月的 Simate(Silicon Mate)发布首版通用物理快系统 Simate-beta,展示记忆、长程任务、精细操作与任务适应能力。据公司提供、更新于 2026 年 9 月 23 日的 RoboDojo 榜单,Simate-beta 以平均 Score 33.95 排名第一,对应 SR 为 27.96%,团队称参评基础模型未针对该榜单专门优化。公司同时开放 AutoResearch 研究平台内测,称清华、MIT、港科大等高校研究者已参与,并已连续完成多轮每轮数亿元人民币融资。

    rch引擎 :自动接棒,把剩下的实验拆解、跑通、反馈全流程自动化。 最终结果也揭晓了,他们靠这套方法在RoboDojo拿下了第一。 更关键的是速度。 Simate从成立到登顶RoboDojo,前后只用了三个月。 真正的机器人研发,底层穿透了模型代码、数据管线、训练集群、评测环境、真机反馈,以及过去数月甚至数年的实验记录。 归根结底,这依然是「上下文」的问题。Agent需要一个能够调度一切的超级接口。 为此,Simate搭建了一套三层架构:SiPAI + AutoResearch + AI-native Infra。 这是一套原生面向「自动化研究」的可插拔模型框架。 只有这样,Agent拿到研究课题后,才能精确知晓:该改哪个模块?改动会波及什么?最后又该如何验证? 目前,Simate已经完成了这套基础设施的搭建,成功接入了世界模型、世界动作模型、VLA、VLM等多种主流架构。 无论是人类研究员还是Agent,都能自由组合组件、调整局部实现,并沿用统一的训练与评测流水线。 如果说SiPAI提供了一份静态说明书,那么AutoResearch解决的就是动态信息差: 研究推进到哪了?以前踩过什么

    匹配字段正文

  4. TechCrunch AI

    Google 在印度测试通过 Gemini 和 AI Mode 直接购买 Flipkart 商品

    Google 开始在印度测试让用户在 Gemini 和 AI Mode 中直接购买沃尔玛旗下 Flipkart 的商品,部分用户会在指定商品列表上看到 Buy 按钮,点击后进入 Flipkart 结账流程而无需离开 AI 界面。该测试目前仅面向部分用户和少量商品,涵盖智能手机、电子产品与手机配件,Google 计划在 10 月晚些时候、印度节庆购物季前扩大范围。Google 此前推出面向 AI 智能体与零售商交互的 Universal Commerce Protocol(UCP),并持有 Flipkart 少数股权,2024 年投资约 3.5 亿美元。

    echnology aimed at making purchases possible through its AI services. Earlier this year, it introduced the Universal Commerce Protocol (UCP) as an open standard designed to let AI agents interact with retailers across the shopping journey, including checkout. Google said at the time that the technology would allow shoppers to buy eligible products through Gemini and AI Mode using a Google-hosted checkout experience. The company has since expanded UCP with other capabilities, including allowing s

    匹配字段正文