←搜索结果

按匹配度 · 共 429 条结果 清除搜索

星期四

  1. The Rundown AI

    Anthropic Claude 将蛋白质设计纳入能力范围

    Anthropic 的 Claude 基本自主完成蛋白质设计流程,设计结果经实验室验证,在 15 个靶点中的 14 个产生有效分子。Mythos Preview 和 Opus 4.8 仅凭一份专家提示词、互联网与工具开展任务,分子结合成功率达 22%–35%,高于 Anthropic 所称的行业典型水平 10%–15%;实际合成和测量由 Twist Bioscience 与 Adaptyv Bio 完成。

    e org and let them figure it out. And enterprise AI is harder to begin with, navigating security, large data complexity, and privacy. Uber's answer was the scalpel. They call them Agentic Pods, and each is only two people: one AI-proficient engineer and one domain expert from Finance, Marketing, Ops, etc., running a surprisingly short 10-day sprint. Shadow the expert, build alongside them, ship. The result: a financial pacing report that took a key player two full days now runs in 10 minutes. Th

    匹配字段正文

星期三

  1. Hugging Face

    IBM 研究:智能体到底需要多少记忆?

    IBM 研究团队在 AppWorld 的 585 个多步任务上测试八款模型,发现智能体记忆存在三种模式:能力强的模型用完整指南集收益最大,DeepSeek-V3.2(671B MoE)任务完成率提升 9.5 个百分点;较弱模型用精选检索更有效,gpt-oss-120b(117B MoE)提升 16.1pp 且 token 只增加约 5%;已饱和的模型如 GLM-5(745B MoE)则没有可测收益。这里的记忆指 ALTK-Evolve 从智能体自身成功与失败轨迹中提炼的指南集,推理时注入上下文,不更新模型权重,因此可跨模型迁移。研究还指出生产环境中提示词缓存是主要成本杠杆,并计划训练基于结果信号的选择器、探索面向极弱模型的教师蒸馏记忆。

    el, not inside it "Memory" here doesn't mean replaying a past transcript. It means a guideline set — strategies that worked, mistakes to avoid, and edge cases — distilled from the agent's own prior trajectories. The loop is straightforward: The agent attempts tasks and produces trajectories. ALTK-Evolve extracts behavioral guidelines from both its successful and unsuccessful runs. It consolidates those guidelines into a reusable set. At inference time, the agent receives either the full guidelin

    匹配字段正文

星期六

  1. Prime Intellect精选

    Prime Intellect 用 nanoGPT 速通实测 18 个前沿模型的自主研究能力

    Prime Intellect 在 nanoGPT 优化器速通任务上对 18 个前沿模型各跑多次自主实验,单次最长八天、每次 8xH200s,共 153 次运行,称这是该规模下首个公开实验。没有任何一次运行提出全新方法,获胜思路都与现有文献相似,但 Fable 5 和 Opus 5 明显领先其他模型。差距体现在实验选择、执行严谨度和对噪声结果的处理上,强模型会用三个种子验证临界结果、在配方变化后重测旧结论,Opus 5 重开 β2 调参并刷新记录。全部 trace、scratchpad、监控报告与 harness 均已公开。

    uating AI research capabilities. We were especially uncertain about what to expect from newer models such as Claude Fable 5, Kimi K3, and GPT-5.6 Sol. In our previous experiments, agents struggled to come up with new ideas. One potential reason is that they over-focused on existing PRs. This time, we didn't give them access to the internet at all. The most striking result is the gap between models. It appears at every stage of the research process: which experiments they choose, how carefully th

    匹配字段正文

星期五

  1. METR Notes

    METR 研究:AI 是否带来了发现加速

    METR 发布分析,用公开发现数据检验 AI 是否带来加速:网络安全漏洞发现明显加速,数学成果有一定加速但更难客观衡量,算法优化领域尚未出现显著加速。结论仅基于公开发现,AI 实验室内部未披露的成果可能未被计入。cURL 漏洞从 2025 年的 9 个增至 2026-06-24 的 36 个,其中 15 个标注 AI;Firefox CVE 从 2025 年的 210 个增至 2026-08-04 的 342 个;OpenSSL 从 2025 年全年的 6 个增至 2026-08-05 的 39 个。数学方面,Smale 问题清单中的 Jacobian 猜想由 Alpöge 与 Claude Fable 在 2026 年给出反例,Green 清单的 Problem 44 和 Problem 100 的 sofic 部分也已被解决。nanoGPT、CIFAR-10、Gurobi、MIPLIB、Stockfish、矩阵乘法指数等优化类指标均未显示明显加速。

    e reasons to be skeptical of the magnitude. Early Work on Monitorability Evaluations We show preliminary results on a prototype evaluation that tests monitors' ability to catch AI agents doing side tasks, and AI agents' ability to bypass this monitoring. How Does Time Horizon Vary Across Domains? We build on our time-horizon work and analyze 9 benchmarks for scientific reasoning, math, robotics, computer use, and self-driving in terms of time-horizon trends; we observe generally similar rates of

    匹配字段正文

星期四

  1. Anthropic:The Institute

    Anthropic 研究多智能体系统的行为模式与失效问题

    Anthropic 发布多智能体系统研究,用漏洞挖掘、协作建游戏、定价博弈和冲突迁移等实验观察 Claude 各代模型的行为差异。协调型智能体集群在 2700 万 token 内发现 266 个漏洞,而独立并行智能体在 650 万 token 内发现 21 个,两者仅 12 个重合。研究还发现智能体行为方差低易同时犯错、可迅速形成价格共谋,并在目标冲突时互相部署恶意代码。

    Vulnerabilities found vs. tokens sampled: coordinated Mythos Preview agents found 266, coordinated Opus 4.8 agents found 41.

    的 token 上似乎相当。 这两种方法在很大程度上是互补的:它们之间只有 12 个共同漏洞。协调型集群能够将注意力集中在它认为最容易挖掘漏洞的地方,而独立智能体则被预先分配了搜索位置。集群中的智能体为自己构建了工具,并学会了专精于特定类型的漏洞发现。 我们预测,未来这种专精化与协调将胜过无协调的暴力搜索。 In the experiment above, agents in the agent swarm don’t directly rely on one-another’s work: if one misses a bug, it won’t directly undermine the work of another. But when agents do depend on one-another, coordination gets much more difficult. Larger software engineering projects are one place this matters: they typically develop rich—and dyn

    匹配字段正文

星期三

  1. Google Research精选

    Google 将 AMIE 推进到实时视频问诊,随机研究显示达到专家级水平

    Google Research 发布 AMIE (Video),基于 Gemini 和 Project Astra 实现实时视频临床问诊,可感知非语言线索、引导虚拟体格检查并同步进行诊断推理。研究采用异步多智能体架构,由三个专职智能体并行处理对话、推理与视听感知,以维持自然对话延迟。在 100 个场景、300 次实时问诊、30 名认证初级保健医生参与的随机 OSCE 研究中,临床评估者在病史采集、诊断准确性和沟通质量上给 AMIE (Video) 的评分与初级保健医生相当,在引导体格检查方面显著更高;患者演员更偏好视频界面。研究全部使用专业患者演员模拟场景,尚未在真实患者中验证。

    Advancing AMIE towards expert-level audio-visual clinical consultations

    to patients at natural conversational speed while simultaneously performing careful clinical reasoning and continuously processing visual and auditory streams. Currently, a single agent cannot satisfy all these requirements. Deep reasoning takes time, but conversational pauses erode patient trust and rapport. To address this challenge, AMIE (Video) uses an asynchronous multi-agent architecture that divides labor across three specialized agents working continuously in parallel: This decoupled des

    匹配字段正文

星期二

  1. Hugging Face

    考虑 ACE?ALTK-Evolve 能以更少 Token 实现

    ALTK-Evolve 通过按模型能力调整指南投放量,在 AppWorld 内部对比中以更低推理成本取得与 ACE 相当或更好的准确率。强模型配置的成本约为 ACE 的 40%,弱模型以约七分之一成本获得 56.0 分,对比 ACE 的 54.8 分。两者都保留带计数的经验指南,但 ACE 每步注入完整 playbook,ALTK-Evolve 可选择性检索或投放完整集合。

    of rules. A lesson five different tasks discovered is a different object from one that appeared once, and both are worth keeping. So on the core question — should you compress an agent's hard-won lessons into a tidy summary? — ACE and ALTK-Evolve give the same answer: no. Count them, don't collapse them. ACE's per-bullet counters and our support counts are two spellings of the same idea. Where we differ Two places: how the memory is built , and how it's delivered — and it's the delivery differe

    匹配字段正文

  2. LMSYS Blog

    LMSYS 发布 Unified Radix Cache:用一棵树统一混合模型前缀缓存

    LMSYS 发布 Unified Radix Cache,用单一 token 基数树统一混合模型的前缀缓存,把 full attention KV、sliding window attention KV 和 Mamba checkpoint 作为组件挂到同一拓扑上,HiCache 原生跨 GPU L1、Host L2 和外部 L3 分层。多轮基准中 L3 在 DeepSeek-V4-Flash 上保持约 98% 命中率、Inkling-Small 上为 96.8%;SWE-bench 轨迹上会话感知配置的 TTFT 比普通 HiRadixCache 加 LRU 低 2.9% 至 16.6%。实验性 Rust 树核心在滑动窗口负载 176 至 200 轮上 TTFT 最多降低 42%。

    prevent stale requests that finish after a close or reopen from restoring released references. We evaluate DeepSeek-V4-Pro and Qwen3.5-397B-A17B with TP8 and HiCache on SWE-bench agent trajectories. The baseline uses ordinary HiRadixCache with LRU. The comparison enables Unified Radix Cache and --enable-session-radix-cache. Because this changes both the cache implementation and the eviction policy, the observed differences should not be interpreted as an isolated ablation of session awareness.

    匹配字段正文

星期二

  1. Johann Rehberger / Embrace The Red

    劫持 LiteLLM:流量拦截、密钥窃取与工具调用注入

    安全研究者 Johann Rehberger 展示了针对 AI 网关 LiteLLM 的一组红队 TTP:攻击者只需拿到 LITELLM_MASTER_KEY 等代理管理员凭据,通过 /model/update 修改 api_base 和 use_litellm_proxy 两个设置,即可把全部推理流量改道到恶意网关。改道后受害者会把后端 LLM 提供商的真实密钥发给攻击者,攻击者再用 async_post_call_success_hook 等回调注入文本或伪造工具调用,由于修改发生在推理之后,可绕过提示词层面的防御。文章同时给出 api_base 变更告警、凭据轮换、出站限制等检测与缓解建议,并指出该思路原则上适用于其他 AI 网关产品。

    s callback and hook system is a supported extension point for modifying responses at the forwarding layer. Injecting Tool Calls Even more interesting though, if the clients are AI agents with tool access, an injected response can carry a tool-call. Because the output is changed after inference, this bypasses prompt-level defenses. It does not by itself bypass client-side tool authorization (unless you run in yolo mode). Pretty scary stuff. Demo Walkthrough with Screenshots The manual sequence be

    匹配字段正文

星期五

  1. Google Research

    Google Research 发布 Science One Framework:用证据链实现可验证的自主科研

    Google Research 发布 Science One Framework,一个通过原生构建证据链来消除幻觉的自主科研原型,并配套 CoE Audit 自动评估协议。在 ADRS 基准的 75 篇生成论文上,基线系统引用幻觉率最高达 21%,而该框架实现零虚假引用和完全可验证的分数,同时在 MLE-Bench 和 Parameter-Golf 等基准上达到 SOTA。该框架为实验性研究原型,并非生产就绪工具。

    n automated protocol to evaluate the integrity of AI-generated papers. Large language models (LLMs) are increasingly being deployed not just as coding assistants but as autonomous agents capable of conducting end-to-end scientific research workflows. Recent systems (e.g., Sakana’s AI-Scientist , AutoResearchClaw , DeepScientist , AI-Researcher ) can review literature, formulate hypotheses, execute experiments and write complete manuscripts that are comparable to human-authored papers. However, a

    匹配字段正文

星期三

  1. LMSYS Blog

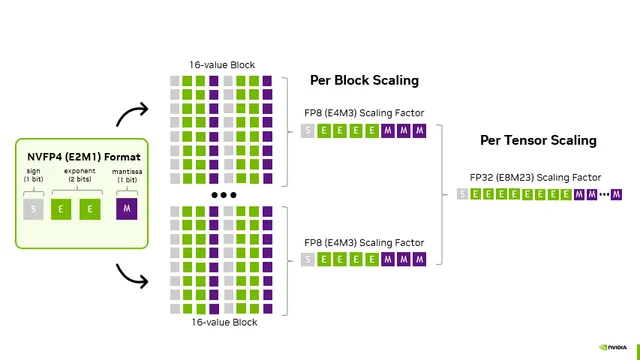
    LMSYS 在 Miles 中实现 Blackwell 原生 MXFP8 与 NVFP4 强化学习配方

    LMSYS 在 Miles 中实现了两种 Blackwell 原生强化学习配方:端到端 MXFP8,以及面向 MoE 专家的逐 token NVFP4,覆盖 checkpoint 转换、Megatron 训练、SGLang rollout 与在线权重更新。在 8x B200 上对 Qwen3-30B-A3B 的配方消融中,BF16 与五种低精度配置的原始 reward 曲线高度重合,MXFP8 和 NVFP4 均缩短了 rollout 时间。NVFP4 采用在线逐 token 激活缩放,并支持高精度或反量化 backward 模式,相关改动已提交至 TransformerEngine、FlashInfer、SGLang 等上游仓库。

    NVFP4 two-level scaling with FP32 tensor scale and E4M3 block scales

    ful even before the training path is fully accelerated. Beyond this ablation, humans& uses the same recipe family and components in production for large-scale, long-context, multi-agent asynchronous RL research. Online NVFP4 Model Serving The same per-token NVFP4 recipe can serve FP8/BF16 model checkpoints with online post-training quantization (PTQ), delivering good model quality without calibration artifacts, while keeping compute performance on par with traditional NVFP4 serving. Online per-t

    匹配字段正文

星期二

  1. Anthropic:The Institute精选

    Anthropic 用 Claude Mythos Preview 发现 HAWK 与 AES 的密码学弱点

    Anthropic 研究人员用 Claude Mythos Preview 改进了对后量子签名方案 HAWK 的攻击,将有效密钥强度减半,并把小尺寸 HAWK-256 的密钥恢复成本从 2^64 降到 2^38。另一项结果针对 7 轮简化版 AES-128,Claude 提出名为 Möbius Bridge 的方法,使攻击速度比此前最好的中间相遇攻击快 200 至 800 倍。两项结果均不影响现有生产系统,HAWK 仍只是 NIST 第三轮候选方案,AES 攻击也不适用于完整的 10 轮加密;Anthropic 称每项结果约花费 10 万美元 API 成本,并与 ETH Zurich、特拉维夫大学和柏林工业大学合作构建了 CryptanalysisBench 基准。

    easons making the scheme (as it currently stands) an attractive PQC signature candidate. Discovery process To find the attack, Claude Mythos Preview worked semi-autonomously in an agentic harness, with occasional human guidance and nontechnical direction. Mythos found the attack after an extensive literature review to understand the state of the art, and substantial mathematical reasoning and computational experiments. After finding the attack, Mythos implemented an end-to-end verification pipel

    匹配字段正文

星期五

  1. Anthropic:The Institute

    Anthropic 与 Andon Labs 发布 Drone-Bench,评测 AI 模型自主操控无人机

    Anthropic 与 Andon Labs 合作开展 Project Pilot,把无人机在室内定位并跟踪指定人员的任务拆成重建、定位、导航、检测、跟随五个子任务,并据此构建基准 Drone-Bench,由 Andon Labs 对 15 个模型进行评测。表现最好的是 Claude Fable 5,除重建外的各项子任务均超过人类与 AI 团队协作的基线,但因重建误差在定位和导航中累积,它仍无法自主跨房间飞行。Anthropic 指出,模型能力前沿约领先其稳定表现六个月,Fable 5 当前的平均水平大致相当于 2026 年初前代模型的一次性最佳表现。

    Drone-Bench step chart: four of five tasks reach near 100% of baseline by mid-2026, while Reconstruct lags at about 47%.

    ject Fetch: Phase two, we’re already seeing improvements in model capability such that their ability to use off-the-shelf robots is on track to approach the ease with which coding agents use software tools. Working again with our partners at Andon Labs, we developed a new series of demonstrations and evaluations that assess AI models’ ability to use a flying drone to autonomously perform a simple locate-and-follow task of the kind used in aerial surveillance, culminating in a new benchmark: Dron

    匹配字段正文

星期四

  1. Google Research

    Google Research 发布 SymptomAI:面向日常症状评估的对话式 AI 智能体

    Google Research 发布研究论文 SymptomAI,用 Gemini Flash 2.0 驱动的对话式智能体完成端到端症状问诊与鉴别诊断(DDx),并在 n=13,917 的全国随机研究中与真实临床医生的评估对比。由三名认证临床医生盲评,超过 50% 的案例中临床医生更偏好 SymptomAI 生成的 DDx,且 SymptomAI 的 DDx 更常包含参与者事后从医疗提供者处获得的真实诊断。研究还发现,主动追问的智能体策略显著优于无提示的 Base 条件,且 SymptomAI 诊断出的呼吸道感染与参与者 Fitbit 在问诊前数日的生理信号变化相吻合。所有诊断与标签仅用于研究分析,不构成确诊或官方医疗评估。

    Four smartphone screenshots display a conversational Symptom Checker research app collecting neck pain symptoms, showing a diagnosis summary, and prompting a feedback rating.

    SymptomAI: Towards a conversational AI agent for everyday symptom assessment July 22, 2026 We present a first-of-its-kind research of AI for differential diagnosis and symptom checking through a national-scale study. A large proportion of clinical diagnoses can be derived from language-based interviews alone. These diagnostic interviews are typically conducted by clinicians through doctor-patient interactions during in-person or remote visits. While these interactions are the gold standard for s

    匹配字段正文

星期一

  1. The Next Platform

    Google 用强化学习实现量子纠错

    Google Quantum AI 团队在 Nature 发表研究,用强化学习让量子计算机在检测到错误时实时调整控制参数,无需停机重校准。该方法在 Willow 超导量子芯片上使逻辑错误率稳定性提升 3.5 倍、错误率降低约 20%,智能体可管理超过 1000 个控制参数,数值模拟中可达 40000 个。研究团队称这为容错量子计算提供了更智能的控制路径。

    other qubits. This can lead to errors, and error-prone quantum systems are neither practical nor useful. AI For QEC A lot of work is being done to see how AI – both generative and agentic – can help address error correction in quantum systems. For example, scientists from the University of Pennsylvania and Hao Tang of Peking University in China addressed the issue in a research paper early last year. Nvidia in April ran out Ising, a family of open source AI models that the vendor said can provid

    匹配字段正文

星期四

  1. Johann Rehberger / Embrace The Red

    从间接提示注入到 macOS Terminal 的 DNS 数据外泄

    Johann Rehberger 披露其 Terminal DiLLMa 后续研究:macOS Terminal 曾允许特定 ANSI 转义码序列发起 DNS 请求,攻击者可借间接提示注入让 LLM CLI 工具读取表格数据并以 DNS 请求外泄。该问题已于 2025 年 11 月 3 日发布的 macOS Tahoe 26.1 中修复,作者获致谢。作者指出 LLM 集成的 CLI 应用常未处理 ANSI 转义字符,建议默认用类似 cat -v 的方式编码控制字符,并提供了 Python 与 Go 的编码函数。

    Ekoparty in 2024, where he talked about injecting ANSI Escape Codes into log files. It’s a great talk, I recommend watching it. How could this be meaningfully exploited? LLMs and Agents! Rendering ANSI Escape Codes with AI Agents! Leon Derczynski discovered that LLMs can emit ANSI escape codes, e.g. the ESC (ASCII 27). When I saw that, it seemed like a great way to hijack AI agents and LLM CLI tools running on the command line and to exfiltrate data. Proof-of-Concept Exploit Here is a demo that

    匹配字段正文

星期三

  1. Hugging Face精选

    推出 Real World VoiceEQ:衡量语音 AI 的人类交互质量

    Real World VoiceEQ 以超过 100 万次人工评分评估 40 多个专有及开源语音模型,覆盖 ASR、TTS、S2S 和语音理解的 15 多个维度、60 多项指标。评测显示,没有单一模型在所有能力上领先,许多系统更擅长说而非听,且在口音、噪声、情绪和长对话等真实场景中的表现低于传统基准所呈现的水平。自动评估器适合答案明确的任务,但涉及声学语境、感知和社会解释时仍无法取代人类听众。

    variation of any category we evaluated. Some systems recognized emotion exceptionally well but struggled to respond naturally. We found that access to audio did not guarantee that agents used the paralinguistic information it contained. Some systems remained largely transcript-driven, relying on the words being spoken while overlooking cues such as tone, pacing, hesitation, emphasis, and volume. Humans naturally use these cues to infer confidence, uncertainty, frustration, sarcasm, and empathy.

    匹配字段正文

星期二

  1. Cognition 模型 / Devin 博客

    Cognition 实测:Fable 5 单价翻倍却比 Opus 4.8 更省

    Cognition 在 FrontierCode 1.1 上跑了 3000 次评测,比较 Opus 4.8 与 Fable 5 分别主导 Devin Fusion 时的成本与得分。Fable 5 每 token 价格是 Opus 4.8 的两倍,但搭配同一廉价 sidekick 后单次成本反而更低(1.86 美元对 2.04 美元),得分更高(60.7 对 54.6)。原因是 Fable 主导时平均只走 11.5 轮、输出 token 约为 Opus 的三分之一,且 81% 的运行中主导模型从不亲自改代码。

    both models on FrontierCode 1.1 using our new Fusion architecture, Fable cost less. Unsurprisingly, it also scored higher. This post explains why, and what that means for pricing agentic work. Introduction Everyone who runs coding agents knows that stronger models give you better results, but you eat the cost. When we introduced Devin Fusion, we showed a way out: keep a frontier model in charge, let it delegate to a cheaper and faster sidekick, and you get frontier-level performance at 60% lowe

    匹配字段正文

星期四

  1. Anthropic:The Institute

    Anthropic 研究:Claude 在机器人任务上的表现取决于控制接口

    Anthropic 发布研究,测试多个语言模型在经典控制、运动导航和机械臂操作任务上的表现,并构建了 Embody 基准套件。结果显示模型能力高度依赖与机器人的连接方式,直接驱动关节时大多失败,而监督预训练控制器或使用简单朝向工具时能完成真实导航和操作任务。在 LIBERO 直接操作中完整任务成功率仅 0 到 5.5%,接入 VLA 策略后各模型成功率大幅提升,但最强模型仍不及 MolmoAct 单独运行。

    Bar graph showing per-model embodiment score by interface. Mythos Preview scores the highest at 0.389, while Opus 4 scores the lowest at 0.115.

    environments. To address this, we retain the inverse pendulum and hopper tasks as control tasks but also introduce a new task based on pinball arcade machines. In TwinFlipper, the agent controls a set of flippers and seeks to maximize the ball’s total airtime—the cumulative amount of time the ball remains above a specified height threshold while not touching anything—before it drops below the flippers. Although a naive solution is to just slam the ball upwards, much more airtime can be gained by

    匹配字段正文

星期六

  1. Lilian Weng:Lil'Log

    Lilian Weng 长文梳理 harness engineering 与自我改进

    Lilian Weng 在 Lil'Log 发布长文,围绕 harness engineering 如何推动递归自我改进,梳理了工作流自动化、文件系统持久记忆、子智能体与后端任务三类设计模式。文章进一步综述 ACE、MCE、Meta-Harness、ADAS、AFlow、STOP、Self-Harness、AHE、AlphaEvolve、Darwin Gödel Machine 等自改进与进化搜索工作,并指出评测器模糊、上下文与记忆生命周期、负面结果、多样性崩塌、奖励攻击等瓶颈,认为人类应在合适抽象层提供监督。

    Harness Design Patterns Pattern 1: Workflow Automation; Pattern 2: File System as Persistent Memory; Pattern 3: Sub-agent and Backend Jobs; Case study: Coding Agent Harness; Harness Layer vs Core Intelligence?; Harness Optimization The concept of recursive self-improvement (RSI) dates back to I. J. Good (1965), where he defined an “ultraintelligent machine” as a system that can surpass humans in all intellectual activities and design better machines to improve itself. Yudkowsky (2008) used the p

    匹配字段正文