←搜索结果

按匹配度 · 共 123 条结果 清除搜索

星期二

  1. 小米 MiMo 官网发布与博客

    小米详解 MiMo-V2.5 推理系统优化实践

    小米 MiMo 团队发布 MiMo-V2.5 系列推理系统的端到端工程实践,覆盖 KVCache 管理、分层缓存、SWA 感知前缀缓存树、调度策略、Prefill/Decode 执行流水线与多模态优化。MiMo-V2.5-Pro 共 70 层,其中 10 层 Full Attention、60 层 SWA,滑动窗口为 128,Hybrid SWA 使计算量与 KVCache 存储降至 Full Attention 的约 1/7。团队称上线以来服务端 KV Cache 命中率平均 93%,重度用户可达 95% 以上,并将部分优化以 PR 形式回馈 SGLang 社区。

    Attention FLOPs vs sequence length: Full Attention vs Hybrid SWA, roughly a 7.0× compute reduction

    varies greatly across different model architectures, and access patterns also differ. As shown below, MiMo-V2.5-Pro and MiMo-V2.5 rank second in KVCache efficiency, trailing only DeepSeek-V4-Pro and DeepSeek-V4-Flash. It is worth noting that actual cost differences do not strictly correspond to KVCache size ratios, as there are fixed compute and memory access costs independent of sequence length. However, in long-context scenarios, the overall trend holds: the gains are marginal for short seque

    匹配字段正文

星期五

  1. LMSYS Blog

    SGLang 与 Miles 在 NVIDIA Vera Rubin 上的适配与优化

    LMSYS 团队提前拿到两个 NVIDIA Vera Rubin 节点(8 块 GPU),把 SGLang 推理和 Miles 强化学习训练搬上该平台。推理侧针对 Kimi K3 NVFP4 调整了 attention、MoE/通信和 KDA 内核,例如更深的 MLA 流水线在 batch 16、128k 上下文下快 16%,融合 MoE 尾部每步减少 276 次内核启动、端到端提升 5.9%。训练侧 Miles 用 SGLang 做 rollout、Megatron 做训练,在单托盘 4 块 GPU 上开箱跑通 Qwen3-30B-A3B 的 GSM8K 训练,奖励从约 45% 升到 95%,并在 Vera CPU 上以 64 个沙箱运行 SWE-bench Verified 的智能体 RL。

    Deeper MLA pipeline using Vera Rubin shared memory

    ,024 response tokens): training converges as expected, with reward rising from about 45% to 95% over 50 rollouts (Figure 3), which matches the GB300 reward growth curve perfectly; DeepSeek-V4-Flash (4-layer, FP8) on GSM8K (32 prompts × 8 samples per step, up to 256 response tokens): the FP8 path runs end-to-end for both rollout and training Figure 3. GSM8K training reward over 50 rollouts, Qwen3-30B-A3B (256 prompts × 8 samples per rollout, up to 1,024 response tokens), GB300 vs Vera Rubin. Thes

    匹配字段正文

星期六

  1. MarkTechPost

    决策 AI 模型解析:TypeSafe Jev 与 Fastino GLiDE、GLiNER2.5-Decide 及开源竞品对比

    决策 AI 模型是一类返回选择、分数或概率而非生成文本的模型,TypeSafe 在隐身两年后推出 Jev,Fastino Labs 三周内跟进两款竞品。Jev 支持 Choice、Score、Noul 三种原语,定价为每百万输入 token 0.042 美元、输出免费,TypeSafe 称端到端响应为 70 至 500 毫秒。在 TypeSafe 的 4 项工作流评测中,Jev 以 67.8% 平均准确率、每例 0.4 秒追平 Claude Sonnet 5,但落后最强前沿配置 6.3 个百分点。

    G edge network orchestration A new arXiv paper used Jev to interpret service contracts at the network edge. At matched correctness, Jev cut median decision latency by 22.4% versus DeepSeek and 61.9% versus Gemini. 5. Real-time game agents TypeSafe’s Doom demo ran Jev at 10 queries per second. The team estimated the cost at roughly $7 per hour. Competitor Landscape: 7 Decision Models Compared The table below covers Jev, its closest commercial rival, and the leading open-weight options. All specs

    匹配字段正文

星期四

  1. SemiAnalysis

    SemiAnalysis 发布 ClusterMAX 3.0 GPU 云评级,覆盖 77 家 neocloud

    SemiAnalysis 发布 ClusterMAX 3.0,对 77 家 neocloud 做全面评测,市场覆盖范围从 2.0 版的 209 家扩大到 323 家,并访谈了 200 多名终端用户。Nebius 与 CoreWeave 同列 Platinum,Google Cloud 与 Oracle 进入 Gold,Azure 降至 Silver,Crusoe 降至 Bronze,全球仅 19 家 neocloud 获得奖章评级。评测分审计、性能、可靠性三阶段,涵盖 GPU 计算、网络、存储、编排、监控与故障注入,并新增 Bronze 与 Underperforming 之间的 Participation Ribbon 档。

    epending on what is supported by the chips in the cluster. We use a common set of shapes for different gate up and down projections at varying batch sizes in the Kimi K2.5, K3 and DeepSeek V3, V4 Pro models. We then test GEMMs, GEMV bandwidth, and MAMF (Maximum Achievable Matmul FLOPS, from Stas Bekman), which runs a sweep for a while on each GPU, per precision, using cuBLASLt (or rocBLAS). We report FLOPs for all of our GEMM tests. We also test memory, through a GEMV test, and nvbandwidth . GEM

    匹配字段正文

星期三

  1. Together AI Blog

    Together AI 详解开源 AI 技术栈:从模型到 harness 的分层实践

    Together AI 发布《The Open Source AI Stack》一文,把开发者从闭源转向开源模型所需的技术栈拆成模型、推理服务商或网关、harness、上下文四层,并称各层相互独立,换模型通常只需改一个配置值。文中以 Kimi K3(1.8T 总参数、104B 激活参数)和 GLM 5.3 Flash(320B 总参数、18B 激活参数)为例说明大模型与小模型的取舍,并列出 OpenRouter、Vercel AI Gateway、LiteLLM 等网关以及 skills、MCP 等扩展方式。作者还建议用大模型规划、小模型实现、大模型审查的三段式工作流,并强调切换模型或任务时新开会话以控制上下文。

    ranks slightly lower overall might be excellent at the kind of coding work you do every day. For reference, the most popular open models in the space right now are GLM 5.3 Flash, DeepSeek V4 Flash , Kimi K3, and MiniMax M3 . These change very rapidly though. After you’ve selected a few models to try out, the next step is to find a provider that hosts them. The way these providers work is that you send them an API request and they run the model on their GPUs. You pay for the input you send to th

    匹配字段正文

星期三

  1. Armin Ronacher AI 博客

    Armin Ronacher 解释大语言模型的推理机制

    Armin Ronacher 解释称,推理轨迹本质上是模型在最终回答前写入暂存区的文本,并通过特殊 token 和解析器与答案分流。他以 GPT-OSS、Responses API 和 DwarfStar 为例,分析推理强度如何由系统提示词塑造,以及禁用原生推理时模型为何可能把思考内容泄露到错误通道。

    why changing the effort invalidates the KV cache. I think closed GPT models call reasoning effort “juice,” since you can ask most models how much juice they have. In DwarfStar for DeepSeek with max reasoning this is added to the system prompt: Don’t Think The destination of reasoning tokens is therefore a learned convention: the model is trained to keep scratch work out of the final channel. Trick it into thinking it is in that channel and it may leak tokens. We have even seen older models, when

    匹配字段正文

星期二

  1. Air Street Press

    ElevenLabs 工程师解析如何缓解 AI 推理算力短缺

    ElevenLabs 研究工程师 Angelos Perivolaropoulos 介绍了如何通过标准工程优化,将语音推理的单 GPU 服务能力从 1 名用户提升至 70 名,架构级改造则可达到约 140 名。连续批处理、FP8 量化、多 token 预测和经蒸馏适配的 FP8 KV cache 是主要手段,其中 KV cache 缩小 2.5x 后,吞吐量从 28 名用户增至 70 名。各项技术会引入延迟、内存上限或质量损失,实际选择取决于具体工作负载。

    t. Where the frontier labs go Seventy is what disciplined engineering gets you. Going further means changing the architecture itself, and here the labs are placing different bets. DeepSeek’s multi-head latent attention squeezes each token’s key-value pair into a small latent rather than storing it in full, which both speeds inference and stretches context toward a million tokens; it was one of the more copied ideas after DeepSeek-R1. Qwen swaps standard quadratic attention for a linear network o

    匹配字段正文

星期三

  1. Browser Use精选

    Claude Fable 5 在 BU Bench 拿下 80% 高分

    Browser Use 用开源 Browser Use 库在 BU Bench V1 上测试 Anthropic 的 Claude Fable 5,得分 80.0%,比第二名 GPT 5.5 高出 12 分。100 个任务中通过 80 个,20 个失败里 16 个判定错误、4 个触发 30 分钟超时,平均每任务耗时 6 分 53 秒,100 个任务 API 成本为 580.87 美元。Fable 的失败主要来自提取错误事实或选错实体、无法充分访问或搜索来源、答案缺乏轨迹支撑,与 GPT 5.5 常因多步骤任务未完成而失败的模式不同。

    minute task timeout. Tasks took 6m 53s on average. That makes Fable slower per task than GPT 5.5, Opus 4.7, and BU 2.0, but faster than Gemini 3 Pro, Qwen 3.6 Plus, Kimi K2.6, and DeepSeek V4 Pro. The cost comparison makes the tradeoff clear. Fable completed many of the long research and browsing tasks that usually separate stronger web agents from weaker ones. These are tasks that require following many steps of reasoning, checking constraints, and returning a structured answer rather than extr

    匹配字段正文

星期二

  1. Together AI Blog

    大规模推理基准测试:编码智能体

    Together Inference Engine 在 Kimi K2.5 编码智能体负载下,以相同的 4× NVIDIA B200 硬件实现了比 TensorRT-LLM 高 31% 的 TPS,并在饱和时保持约 2 倍更优的 TTFT。测试采用约 45k–200k Token 的长提示词和平均 450 Token 的输出;SGLang 因 TP4 内存不足改用 8× B200。性能提升来自 ThunderMLA、定制内核重写及真实流量下的端到端分析。

    Bar chart titled Coding agents with pink and orange bars on dark background with code snippets behind.

    came from treating inference as a full-stack problem: profiling end-to-end, identifying the most expensive operations, and eliminating them one by one. ThunderMLA. Kimi K2.5 uses DeepSeek's Multi-head Latent Attention (MLA) architecture. Standard implementations run two separate kernel launches per decode step. Our ThunderMLA — part of our ThunderKittens kernel library — fuses these into a single megakernel, eliminating launch overhead and the tail effects between them. On representative decode

    匹配字段正文

星期四

  1. Together AI Blog

    Violin:打破语言障碍的开源视频翻译技能

    Together AI 推出完全开源的 Violin 视频翻译工具,通过 ASR、大语言模型翻译和 TTS 语音合成生成译制视频。它还支持基于音视频内容的多模态问答和自然语言选声,不提供声音克隆,并默认以低音量保留原声。GUI、后端模型与智能体技能均以 MIT 许可证开放。

    point that provides high quality multi-lingual transcription at an optimized speed. Then a large language model translates that transcript. Here we leverage the latest advances of Deepseek V4 Pro as default translator. We also enable the user's input of a predefined list of translation rules to maintain the faithfulness and accuracy. Finally, the TTS model generates translated speech, allowing users to specify their desired voice characteristics in plain text. Together-hosted Cartesia’s Sonic 3

    匹配字段正文

星期三

  1. Ahead of AI

    2026 年 1—2 月开放权重 LLM 架构对比:10 组主要模型发布

    作者对 2026 年 1—2 月的主要开放权重 LLM 发布进行架构对比,并补充了 3 月 6 日发布的 Sarvam 30B 和 105B。文章逐一分析 Trinity Large、Kimi K2.5、Step 3.5 Flash、Qwen3-Coder-Next、GLM-5、MiniMax M2.5、Nanbeige 4.1 3B、Qwen3.5、Ling 2.5、Ring 2.5 与 Tiny Aya,重点比较 MoE、混合注意力、MLA、Gated DeltaNet、滑动窗口注意力和 MTP 等设计。作者认为,近期架构普遍加入计算效率优化,但模型表现也很大程度取决于数据质量和训练方案。

    B (Feb 13, 2026); Qwen 3.5 (Feb 15, 2026); Ant Group’s Ling 2.5 1T & Ring 2.5 1T (Feb 16, 2026); Cohere’s Tiny Aya (Feb 17, 2026); Update 1: Sarvam 30B and 105B (Mar 6, 2026) (PS: DeepSeek V4 will be added once released.) Since there’s a lot of ground to cover, I will be referencing my previous The Big LLM Architecture Comparison article for certain technical topics (like Mixture-of-Experts, QK-Norm, Multi-head Latent Attention, etc.) throughout this article for background information to avoid r

    匹配字段正文

星期一

  1. vLLM 官方博客

    vLLM 与 TorchTitan 实现训练推理逐位一致的在线强化学习

    vLLM 与 TorchTitan 开源展示了逐位一致的在线强化学习方案,使 Qwen3 1.7B 的训练与推理数值完全匹配。实验中启用逐位一致性后,模型用更少步骤取得更高总奖励,但当前运行速度比非逐位一致方案慢 2.4x。

    wise training-inference consistency a scalable and reusable feature. If you're interested or would like to contribute, please join these Slack channels: sig-post-training; sig-batch-invariant Related Posts DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.

    匹配字段正文

星期二

  1. Ahead of AI

    标准 LLM 之外有哪些替代架构

    Sebastian Raschka 梳理了标准自回归 Transformer 之外的线性注意力混合架构、文本扩散模型、代码世界模型和小型递归 Transformer。文章比较了这些路线在长上下文效率、生成质量、代码建模和专用推理上的取舍,并认为通用项目目前仍应优先采用成熟的自回归 Transformer。

    From DeepSeek R1 to MiniMax-M2, the largest and most capable open-weight LLMs today remain autoregressive decoder-style transformers, which are built on flavors of the original multi-head attention mechanism. However, we have also seen alternatives to standard LLMs popping up in recent years, from text diffusion models to the most recent linear attention hybrid architectures. Some of them are geared towards better efficiency, and others, like code world models, aim to improve modeling performanc

    匹配字段正文

星期日

  1. vLLM 官方博客精选

    vLLM Sleep Mode 如何实现模型零重载切换

    vLLM Sleep Mode 通过保留进程、内存分配器、CUDA 图和 JIT 内核,将多模型切换从完整重载的 30-100+ 秒缩短至秒级或亚秒级。Level 1 将权重卸载到 CPU RAM,Level 2 丢弃权重并在唤醒时从磁盘重载;两种模式的切换速度比完整重载快 18-200x,预热模型的推理速度比冷启动快 61-88%。

    cial thanks to Vensen Mu, Jeff Aw, Jun Kang Chow, Tun Jian Tan, Pin Siang Tan, Amir Balwel, Ye Hur Cheong, Zhiyao Cen and Kaichao You for developing the Sleep Mode feature and this blog post. Related Posts DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.

    匹配字段正文

星期四

  1. vLLM 官方博客

    SemiAnalysis InferenceMAX 评测解析:vLLM 与 NVIDIA 加速 Blackwell 推理

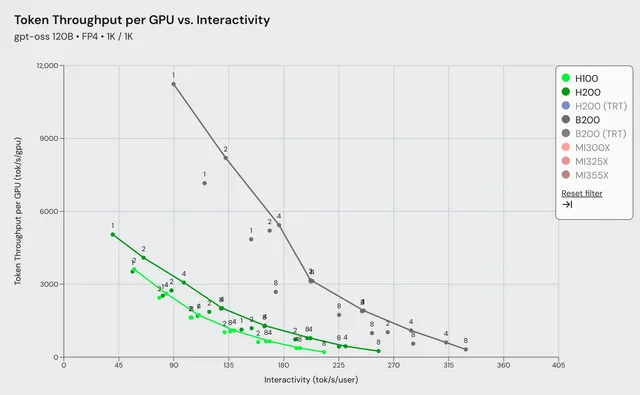
    vLLM 与 NVIDIA 针对 Blackwell 优化大语言模型推理,在相近延迟下,gpt-oss 120B 和 Llama 3.3 70B 的吞吐量较上一代 Hopper 最高提升约 4x。双方通过一百多个 pull request 优化注意力、GEMM、MoE 内核、图融合和异步调度,并加入自动量化后端选择与 FlashInfer 自动调优。SemiAnalysis InferenceMAX 每日更新测试结果,以不同输入输出长度和 Pareto 前沿比较吞吐量与响应速度。

    is ongoing and there are an overwhelming number of improvements on the horizon. Looking ahead, we’re working to unlock significant throughput gains on cluster-scale inference for DeepSeek, Qwen, gpt-oss, and many more through speculative decoding and Data+Expert Parallel (DEP) configurations. With NVIDIA’s gpt-oss-120b-Eagle3-v2, which incorporates Eagle speculative decoding, we anticipate up to 2-3x improvement in throughput. Leveraging DEP, which takes advantage of the 1,800 GB/s low latency

    匹配字段正文

星期日

  1. Ahead of AI

    从零理解 LLM 评估的四种主要方法

    文章讲解评估 LLM 的四种主要方法,包括多项选择、验证器、排行榜和 LLM 评审,并配有从零代码实现。不同方法分别侧重知识准确率、可验证任务、用户偏好和整体回答质量,各有成本、偏差与适用范围,因此模型评估应组合多种方法,并使用贴合目标领域的数据。

    egorize PRMs as “step-level judges,” which are predominantly developed for training, not pure evaluation. (In practice, PRMs are difficult to train reliably at scale. For example, DeepSeek R1 did not adopt PRMs and instead combined verifiers for the reasoning training.) Judge-based evaluations offer advantages over preference-based leaderboards, including scalability and consistency, as they do not rely on large pools of human voters. (Technically, it is possible to outsource the preference-base

    匹配字段正文

星期六

  1. Ahead of AI

    从零理解并实现 Qwen3

    作者用纯 PyTorch 从零实现 Qwen3,通过代码讲解其架构组件,并提供可用于实验或项目的构建模块。文章还介绍了 Qwen3 的 Apache License v2.0 许可,以及从 0.6B 稠密模型到 480B 参数 MoE 模型的多种规模。

    ting, the open-weight 235B-Instruct variant is ranked 8 on the LMArena leaderboard, tied with the proprietary Claude Opus 4. The only 2 other open-weight LLMs that rank higher are DeepSeek 3.1 (3x larger) and Kimi K2 (4x larger). On September 5th, Qwen3 released a 1T parameter “max” variant on their platform that beats Kimi K2, DeepSeek 3.1, and Claude Opus 4 on all major benchmarks; however, this model is closed-source for now; There are many different model sizes available for different comput

    匹配字段正文

星期五

  1. vLLM 官方博客

    深入 vLLM:高吞吐 LLM 推理系统架构解析

    文章系统解析 vLLM V1 如何从单 GPU 离线推理扩展到多 GPU、多节点异步服务。内容涵盖调度器、PagedAttention、连续批处理、前缀缓存、引导解码、推测解码、P/D 分离及分布式请求链路,并说明如何用 vllm bench 衡量延迟与吞吐量。分析基于 2025 年 8 月 9 日的 commit 42172ad。

    "Attention Is All You Need" https://arxiv.org/abs/1706.03762; "Efficient Memory Management for Large Language Model Serving with PagedAttention" https://arxiv.org/abs/2309.06180; "DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model" https://arxiv.org/abs/2405.04434; "Jenga: Effective Memory Management for Serving LLM with Heterogeneity" https://arxiv.org/abs/2503.18292; "Orca: A Distributed Serving System for Transformer-Based Generative Models" https://www.usenix.

    匹配字段正文

星期三

  1. vLLM 官方博客

    vLLM 详解 torch.compile 的工作原理与集成方式

    vLLM 介绍了 torch.compile 的工作原理,以及它如何通过编译缓存、动态批量大小、分段 CUDA Graphs 和自定义编译器 pass 优化大语言模型推理。vLLM V1 默认在在线与离线推理中启用该能力,部分融合优化可带来最高 15% 的性能提升。文章还说明了缩短启动时间、改用更稳定 API 和探索 MPK/Mirage 编译器集成等后续方向。

    M, it’s a core part of the inference pipeline. Combined with caching, dynamic shape support, CUDA Graphs, and custom passes, it enables efficient, scalable LLM serving across any environment. Related Posts DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.

    匹配字段正文

星期六

  1. Ahead of AI精选

    从 GPT-2 到 gpt-oss:解析 OpenAI 开放权重模型的架构演进

    文章解析 OpenAI 的 gpt-oss-20b 和 gpt-oss-120b,并将其架构与 GPT-2、Qwen3 对比。两款模型采用 MoE、GQA、滑动窗口注意力、RMSNorm 和 MXFP4,其中 20B 模型可装入 16 GB 显存,120B 模型可在单张 80 GB H100 上运行。作者还讨论了宽度与深度、专家规模、推理强度控制及模型幻觉等问题。

    trends and developments point towards more, smaller models as being beneficial. This change, at a constant total parameter size, is nicely illustrated in Figure 15 below from the DeepSeekMoE paper. Notably, unlike DeepSeek's models, neither gpt-oss nor Qwen3 uses shared experts, though. To be fair, the small number of experts in gpt-oss could be a side effect of the 20B size. Looking at the 120B mode below, they indeed increased the number of experts (and transformer blocks) while keeping every

    匹配字段正文