SGLang 优化 GLM-5.2 NVFP4 智能体负载:两周内达到 500 TPS
SGLang 团队为 GLM-5.2 NVFP4 智能体负载引入多项优化,在 8xB300(bs=1)上实现超过 500 TPS。默认开启的 Spec V2 重叠运行时消除 GPU 气泡,带来 11% 端到端 TPS 提升;IndexShare MTP 复用 DSA indexer top-k,长上下文下草稿步成本降低约 1.9 倍。TopK-V2 内核将 80K ISL 平均延迟从 40.7 µs 降至 17.5 µs(2.33 倍),1M ISL 下提速 10.17 倍。
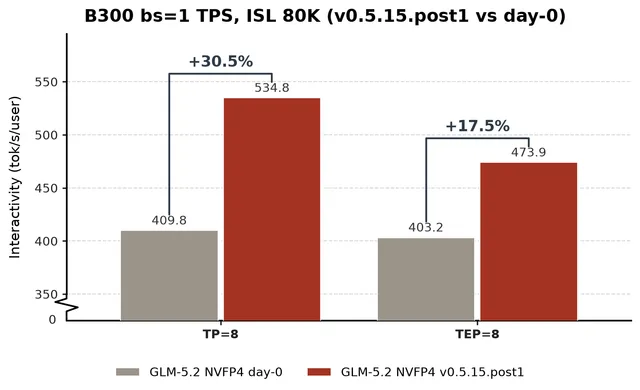
ormance comparison between Day-0 and v0.5.15.post1 on 8 B300 Background GLM-5.2 keeps the same backbone as earlier GLM checkpoints: DSA with a sparse-attention indexer on top of a DeepSeek-V3-style MoE. It adds two major architectural changes: IndexShare for DSA, and MTP with IndexShare and KVShare. SGLang has supported the GLM-5.2-NVFP4 checkpoint since day 0 on (Grace) Blackwell hardware, using trtllm-gen kernels for both sparse attention and MoE. To turn that day-0 stack into a faster, more s
匹配字段正文