←搜索结果

按匹配度 · 共 1363 条结果 清除搜索

星期二

  1. Dwarkesh Patel Podcast & Blog

    Grant Sanderson 谈 AI 与数学的未来

    Dwarkesh Patel 与 3Blue1Brown 作者 Grant Sanderson 对谈 AI 与数学的未来,讨论 AI 在数学上的进展为何快于其他领域,以及这种进展对其他行业意味着什么。Sanderson 认为 IMO 金牌只是又一个基准,数学内部同样存在参差,几何题可被暴力求解而组合题仍难;他还以 Galois 群论为例说明概念突破的验证回路可能长达百年,并谈到 AI 能否在领域之间建立连接、以及数学家的角色可能转向类似策展人的方向。

    a systems, it’s exploring all possible logical consequences of any kind of axiom. Dwarkesh Patel On the point about whether you can provide process-based supervision without Lean, DeepSeek had their DeepSeek Math model. They released a paper on how they trained it, and it was quite interesting. The problem with natural language proofs is you don’t know if it’s correct or not. They have a verifier, and the verifier is trained by a meta-verifier that makes sure that for all the problems they’re tr

    匹配字段正文

  2. Air Street Press

    ElevenLabs 工程师解析如何缓解 AI 推理算力短缺

    ElevenLabs 研究工程师 Angelos Perivolaropoulos 介绍了如何通过标准工程优化,将语音推理的单 GPU 服务能力从 1 名用户提升至 70 名,架构级改造则可达到约 140 名。连续批处理、FP8 量化、多 token 预测和经蒸馏适配的 FP8 KV cache 是主要手段,其中 KV cache 缩小 2.5x 后,吞吐量从 28 名用户增至 70 名。各项技术会引入延迟、内存上限或质量损失,实际选择取决于具体工作负载。

    t. Where the frontier labs go Seventy is what disciplined engineering gets you. Going further means changing the architecture itself, and here the labs are placing different bets. DeepSeek’s multi-head latent attention squeezes each token’s key-value pair into a small latent rather than storing it in full, which both speeds inference and stretches context toward a million tokens; it was one of the more copied ideas after DeepSeek-R1. Qwen swaps standard quadratic attention for a linear network o

    匹配字段正文

星期一

  1. Interconnects

    Interconnects 第 22 期开源模型盘点:Zyphra、Cohere 与 Poolside 拓宽生态版图

    Interconnects 第 22 期开源模型盘点指出,开源模型生态正从少数中国厂商主导走向多元,作者把发布方分为纯模型厂商、大科技公司和产品公司三类。本期收录 NVIDIA Nemotron-3-Ultra-550B-A55B-BF16、Cohere 以 Apache 2.0 发布的 Command A+(218B-A25B MoE)、GLM-5.2、Zyphra 的 ZAYA1-74B-preview、Poolside 的 Laguna-M.1 等模型。作者认为开源模型开发并非由单一类型参与者驱动,这种多样性正是开源生态的优势之一。

    es: “Pure” model makers : These are companies whose stated goal is to train models that are at the frontier, or at least close to it. This includes many Chinese companies, such as DeepSeek, Zhipu, and Minimax, but also Western ones like Poolside, Arcee, and Zyphra. It also increasingly includes sovereign AI players, such as Cohere, Sovereign, Mistral, and Trillion Labs. The recent Mythos episode has woken up some policymakers, which may lead to increased interest in sovereign model training. Big

    匹配字段正文

星期三

  1. Modal 官方工程博客

    Modal 如何用推测解码实现 SOTA 推理延迟

    Modal 本周推出 Auto Endpoints,结合 Blackwell GPU、SGLang 和 Modal Servers,通过推测解码优化延迟。在 Decagon Voice 案例中,基线 p50 延迟约 290ms,优化后削减 100ms,比专有推理提供商的最佳延迟快 60ms 以上。推测解码带来的加速与接受长度近似线性,是降低解码延迟的关键手段。

    trained models and then train them further (”mid-training”) to apply them to our specific task. "Pre-training" — Starting from generic draft models Building off of the work of the DeepSeek team, many models are now released with multi-token prediction (MTP) heads that can be used for speculative decoding. These heads improve quality in training and performance in inference, so they’re something of a no-brainer. But for that same reason, they are first-and-foremost a train-time optimization. Bett

    匹配字段正文

星期一

  1. Interconnects

    GLM-5.2 是开源智能体的转折点

    Interconnects 作者认为 GLM-5.2 是首个在编码智能体框架中真正好用的开源权重模型,社区基准显示它是唯一能与 OpenAI、Anthropic 最新模型同场竞争的开源模型。作者实测用 Fireworks API 在 Claude Code 中调用该模型,整体能力立刻感觉可用,但遇到框架向模型发送图片导致 API 会话中断、需手动清空上下文的问题。作者测算 Claude Opus 4.5 发布到 GLM-5.2 发布相隔 204 天,落在常说的 6 至 9 个月开源与闭源性能差距区间内,并认为这会加剧 token 消耗大户的定价压力,利好开源模型推理与微调生态。

    之一,但那是另一个话题了。有一个在社区中评价褒贬不一的基准测试(尤其是在真正的设计师群体中)——Design Arena 甚至显示 GLM-5.2 击败了 Claude Fable 本身——那个最近被封禁的炒作机器! 在 AI 评论界和研究界中,我尊重的几乎所有人都在亲自使用后称赞了这款模型。社区中如此集中的讨论焦点,此前只有一次在开源模型发布时如此明显——DeepSeek R1。这不是我轻易做出的比较,而当我将 Kimi K2 的发布比作“DeepSeek 时刻”时,GLM-5.2 已经远远超过了那一次。Kimi K2 令人印象深刻之处在于,开源模型性能的大幅进步似乎可以来自中国的任何地方。而 GLM-5.2 所迈出的这一步,更像是 AI 进步的一扇单向门。 Anthropic 凭借 Claude Code 创下的创纪录营收增速,很大程度上是由其作为最佳模型、以及唯一真正能做到这一点的模型所驱动的。GLM-5.2 是众多(即将到来的)开源权重模型中第一个提供可信替代方案的。这一类比非常清晰,就像当年 DeepSeek R1 表明,资源远为匮乏的开源权重实验室也能复现 OpenAI 以

    匹配字段正文

  2. Prime Intellect精选

    Prime Intellect 发布 prime-rl 0.6.0,支持万亿参数规模强化学习

    Prime Intellect 发布 prime-rl 0.6.0,可在重智能体负载下训练万亿参数规模模型,并称能在 28 个 H200 节点上以最高 131k 序列长度训练 GLM-5 完成 SWE 任务,步时间低于 5 分钟、批量 256 条 rollout。该版本采用异步 RL,将训练与推理解耦,并给出 FP8 推理、Wide EP、P/D 分离、KV cache 分层卸载、router replay 以及 FSDP、EP、CP 三维并行等优化细节。这些优化同样适用于 Kimi-K2.7-Code、NVIDIA-Nemotron-3-Ultra-550B-A55B-BF16 等其他大型 MoE 模型。

    RL at 1T Scale: prime-rl Performance Deep Dive

    and backward. FP8 training As noted earlier, trainer↔inference mismatch can hurt your training. To fight this, we use DeepGEMM kernels to perform block-scaled FP8, as proposed by DeepSeek V3. This, contrary to popular belief, doesn't really increase the throughput, due to quantization overhead (except for specific configurations); however, it heavily decreases KL mismatch between trainer and inference, as both now use the same precision, and even the same kernels in some cases. This in turn lea

    匹配字段正文

星期五

  1. Modal 官方工程博客

    Modal 开源 Qwen 系列 DFlash 推测解码模型

    Modal 本周发布面向 Qwen 3.5 397B-A17B 的 DFlash 推测解码模型,并与 SGLang 合作优化性能;同时在 Hugging Face 开源 Qwen 3.6 35B-A3B、Qwen 3.5 4B/9B/27B/35B-A3B/122B-A10B 的 DFlash 草稿模型,在已有 DFlash 基线上再获 5% 至 20% 加速。Modal 称 Qwen 3.5 122B-A10B 在 B200 单节点、并发 1 下可超过 1000 tok/s,并给出接受长度从 3 提升到 9 可将加速从 25% 提升到 3 倍的建模分析。

    ed. You can try that out here. We walk through a sample output from this model below. The chart compares the decode speedup from speculation, over the autoregressive baseline, for DeepSeek-V4 Pro deployed on a single B200 node processing a specific workload. The workload in this case is short sequence length ( 4k tokens/sequence) and high concurrency (batches of 32 sequences). The chart at the top shows the predicted speedup factor at a variety of different draft lengths for several drafters, al

    匹配字段正文

  2. Black Forest Labs Blog

    Black Forest Labs CEO Robin Rombach 在 G7 呼吁支持开放创新

    Black Forest Labs 联合创始人兼 CEO Robin Rombach 在 G7 峰会向 Macron、Trump、Merz、von der Leyen 等领导人发表演讲,呼吁各国政府和产业界让开放且负责任的 AI 开发成为常态而非例外。这家 90 人的前沿 AI 实验室专注视觉“世界模型”,其团队参与开发了 Stable Diffusion 等史上最受欢迎的 5 个开放生成式 AI 模型中的 3 个。Rombach 称其最新开放模型在性深度伪造和儿童虐待材料方面的漏洞比大型科技公司的开放模型少 10 倍以上。

    Our co-founder and CEO urges G7 leaders to back open innovation

    sual generative AI. Our team has co-developed 3 of the top 5 most popular open generative AI models of all time, including Stable Diffusion, and the only open models as popular as DeepSeek. We’ve talked a lot about language models today. They are remarkable. But language is a compressed, and ultimately limited, representation of the world. We are building models that learn from thousands of years of video, and can reason in complex visual environments—the rich, messy, complicated world we actual

    匹配字段正文

星期三

  1. LMSYS Blog

    LMSYS 用 SGLang-JAX 在 TPU 上优化 Ling-2.6-1T:单个 Pallas 内核让 MoE 数据搬运隐藏在计算之后

    SGLang-JAX 现已支持在 TPU v7x 上高效服务 inclusionAI 的 Ling-2.6-1T,其新的 Pallas 融合 MoE V2 内核将 MoE prefill 延迟从 5.16 ms 降至 2.42 ms(降幅 53%),decode 内核延迟从 0.249 ms 降至 0.211 ms。在相同 SGLang decode 基准下,16 块 TPU v7x 的输出吞吐达到 16 块 H200 GPU 的 1.29×(mc=128)至 1.77×(mc=512)。Ling-2.6-1T 为 1T 稀疏 MoE 模型,每 token 激活 63B 参数,含 256 个路由专家、top-8 路由加一个共享专家。

    Ling-2.6-1T decode throughput, TPU v7x vs GPU H200

    [1] Ling-2.6-1T model card [2] Hybrid models meet SGLang (blog) [3] Ragged Paged Attention [4] Fused MoE V1 kernel, tpu-inference [5] Fused MoE V1 kernel adapted in SGLang-JAX [6] DeepSeek-V2 (MLA) [7] Gated Linear Attention (GLA) [8] MiniMax-01 (Lightning Attention) [9] SGLang (RadixAttention) Acknowledgments SGLang-JAX team: jimoosciuc, Prayer, aolemila, neo, leos, pathfinder-pf, Haolin Fu, Qinghan Chen, JamesBrianD, Haoguang Cai, Yuhao Hu, cjx0709, Zhengke Zhou, Yuxin Wei, Lianfang Wang, 0xas

    匹配字段正文

  2. The Next Platform

    Tensordyne 发布 Napier 推理芯片,用对数运算替代矩阵乘法

    Tensordyne 公布其 Napier AI 推理引擎架构,核心思路是把数据转成对数后用加法替代矩阵乘法,官方称相比 Nvidia 和 AWS 的混合架构性能提升一个数量级以上,价格与功耗更低。Napier 采用 3nm 工艺、1380 亿晶体管,支持 NVFP4、FP8、FP16,FP8 稠密算力 2.1 petaflops,配备 144 GB HBM4 和 256 MB SRAM,单芯片功耗 300 瓦,对比 B300 GPU 的 1200 瓦。公司计划 2026 年底开放云端访问,2027 年第一季度向客户交付 beta 版 TDN Pod 系统,2027 年第二季度末开始出货。

    a good idea. If the Tensordyne architecture pans out and can support all of the big inference engines, and Tensordyne can get enough HBM to make them in high volume, this may be a DeepSeek moment for AI hardware. RK Anand, one of the co-founders of Tensordyne, tells The Next Platform that Broadcom is the chip shepherd for the Napier compute engine and that with Broadcom being the third largest buyer of HBM memory on the planet and the third largest buyer of chip wafers from Taiwan Semiconductor

    匹配字段正文

星期一

  1. LMSYS Blog

    LMSYS 发布 DFlash 与 Spec V2 推测解码引擎

    LMSYS 联合 Z Lab 和 Modal 发布 DFlash 推测解码模型与 SGLang 默认的 Spec V2 引擎,DFlash 用块扩散并行起草并通过 KV 注入提升接受长度。在 HumanEval 数据集并发为 1 时,Qwen 3.5 397B-A17B 的 DFlash 模型吞吐达到基线的 4.3 倍以上、MTP 的 1.5 倍。该模型已在 z-lab、modal-labs 和 lmsys 三个 Hugging Face 组织发布,可在 SGLang 中直接部署。

    no impact on model quality. However, many speculative decoding methods, like the EAGLE series and the native multi-token prediction (MTP) modules in recent models like Gemma 4 and DeepSeek-V4, still rely on sequential autoregression – but in the draft model instead of the target. The draft model generates draft tokens one-by-one,a poor fit for modern hardware and a limit on achievable speedup. That’s why Z Lab developed DFlash, which uses a lightweight block diffusion draft model to generate an

    匹配字段正文

星期四

  1. Modal 官方工程博客

    Modal 如何让 FlashAttention-4 更适合 LLM 推理

    Modal 对 FlashAttention-4 内核做了一系列改动以适配 LLM 推理,尤其是解码阶段:PR 2109 支持 FP8 输入(e4m3/e5m2),相对 bf16 基线吞吐最高提升 1.16 倍;PR 1999 与 PR 2104 支持任意 KV page size 并优化性能,小 page size 下吞吐最高提升 2.40 倍。改动还包括调整并行策略(从 query 并行转向 key/value 并行)以及用 cp.async 加载替代 TMA 的 cp.async.bulk 加载以支持不规则全局内存访问。

    Diagram showing output tile generation without and with KV parallelism

    nd so are harder to quantize. Models like gpt-oss combine single-precision attention operations with 4 bit matmuls to get the best of both worlds. However, key model families like DeepSeek-V3 and V4 natively (i.e., from training) support 8 bit attention operations. And other models like the Qwen and Gemma series are sometimes deployed with 8 bit KV caches to accelerate inference. So we added support for 8 bit floats (with either four or five exponent bits, aka e4m3 or e5m2). Relative to the othe

    匹配字段正文

星期三

  1. Browser Use精选

    Claude Fable 5 在 BU Bench 拿下 80% 高分

    Browser Use 用开源 Browser Use 库在 BU Bench V1 上测试 Anthropic 的 Claude Fable 5,得分 80.0%,比第二名 GPT 5.5 高出 12 分。100 个任务中通过 80 个,20 个失败里 16 个判定错误、4 个触发 30 分钟超时,平均每任务耗时 6 分 53 秒,100 个任务 API 成本为 580.87 美元。Fable 的失败主要来自提取错误事实或选错实体、无法充分访问或搜索来源、答案缺乏轨迹支撑,与 GPT 5.5 常因多步骤任务未完成而失败的模式不同。

    minute task timeout. Tasks took 6m 53s on average. That makes Fable slower per task than GPT 5.5, Opus 4.7, and BU 2.0, but faster than Gemini 3 Pro, Qwen 3.6 Plus, Kimi K2.6, and DeepSeek V4 Pro. The cost comparison makes the tradeoff clear. Fable completed many of the long research and browsing tasks that usually separate stronger web agents from weaker ones. These are tasks that require following many steps of reasoning, checking constraints, and returning a structured answer rather than extr

    匹配字段正文

星期二

  1. MiniMax Blog

    MiniMax 详解 MaxProof:用生成式验证器 RL 与进化搜索扩展数学证明

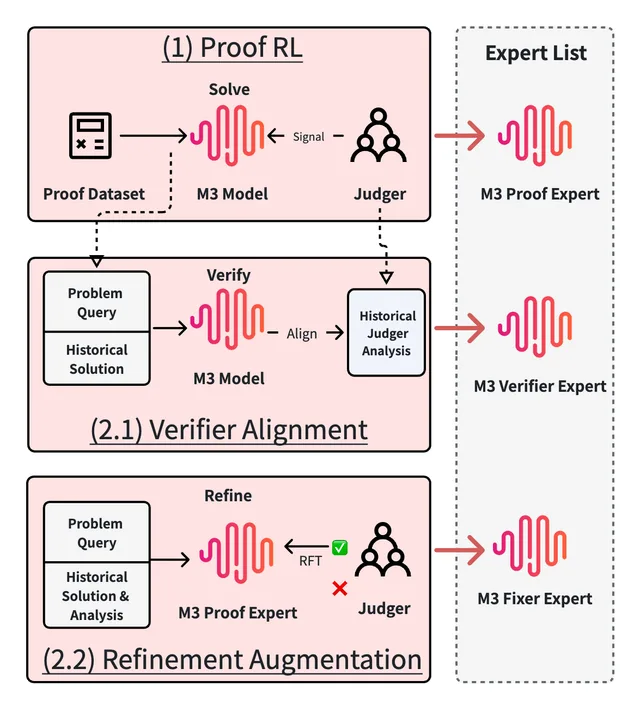
    MiniMax 发布技术博客详解 MaxProof 框架,M3 模型借助该框架在 IMO 2025 和 USAMO 2026 两项数学奥赛基准上均超过人类金牌线。方法分两部分:先训练 Proof Expert、Verifier Expert、Fixed Expert 三个专家模型提升证明生成、错误判断与证明修复能力,再用进化搜索式测试时扩展框架 MaxProof 让 M3 多轮自迭代求解。

    Part 1 Overview: Three-Stage Base Model Enhancement Plan

    l, aligning a verifier, building refinement capability, and designing the test-time scaling framework MaxProof. From Gemini Deep Thinking reaching gold-medal level on IMO 2025, to DeepSeek-Math-V2 becoming the first open-source model with gold-medal-level capability, to SU-01 and NVIDIA Nemotron Cascade2 showing specialized math-contest ability in smaller models, and GPT 5.5 solving long-standing open problems, models are steadily entering harder regions of the mathematical problem space. During

    匹配字段正文

星期一

  1. Qwen Blog精选

    阿里千问发布 Qwen3.7-Plus 多模态智能体模型

    阿里千问发布 Qwen3.7-Plus,一款把视觉与语言统一到单一智能体底座的多模态模型,已在阿里云百炼上线。它可在同一智能体循环中混合执行 GUI 与 CLI 操作,支持屏幕读取、视觉参考写代码、移动应用端到端操作,并适配 Claude Code、OpenClaw、Qwen Code 等框架。官方基准显示其在 Terminal Bench 2.0-Terminus 得 70.3、ScreenSpot Pro 得 79.0、AndroidWorld 得 81.0,同时支持 preserve_thinking 保留历史思考内容。

    A Cross-harness generalization across diverse agent frameworks Call via API on Alibaba Cloud Model Studio . Performance Text Benchmarks Opus-4.6 Max K2.6 Thinking GLM-5.1 Thinking DeepSeek-V4-Pro Max Qwen3.6-Plus Qwen3.7-Plus Coding Agent Terminal Bench 2.0-Terminus 65.4 66.7 63.5 67.9 61.6 70.3 SWE-Verified 80.8 80.2 -- 80.6 78.8 77.7 SWE-Pro 57.3 59.5 58.8 59.0 56.6 57.6 SWE-Multilingual 77.5 76.7 -- 76.2 73.8 75.8 NL2repo 47.6 42.8 41.0 35.5 34.4 41.1 SciCode 51.9 52.2 45.1 -- 41.4 51.3 QwenW

    匹配字段正文

  2. Modal 官方工程博客

    Modal:强化学习本质是基础设施问题

    Modal 官方工程博客指出,当前 LLM 强化学习后训练的瓶颈在于基础设施,而非算法本身。团队总结出三大常见卡点:维护胶水代码、排队等待集群时间、GPU 利用率不足,并开源了一个库供开发者直接使用。Modal 称用户可通过 rdma=True 一行代码启动 RDMA 互联的 GPU 训练集群,并在几分钟内从零扩展到 B200 集群。

    st for proprietary models at the frontier is flat or increasing, thanks to increasing reliance on test-time compute. Fortunately, multiple organizations, from NVIDIA and Google to DeepSeek and Kimi, are releasing excellent models under permissive licenses. While small (here, under a billion parameters) models still have strong fine-tuning potential, for more complex tasks, larger models are the move. They tend to have a higher capability ceiling, better data efficiency, and less catastrophic for

    匹配字段正文

  3. MiniMax Blog

    MiniMax 发布 M3:前沿编码、1M 上下文与原生多模态合一

    MiniMax 正式发布 M3,采用自研 MSA 稀疏注意力架构,支持最高 1M token 上下文,并原生支持图像与视频输入、可操作桌面电脑。官方称 M3 是目前首个同时具备这三项能力的开源权重模型,在 SWE-Bench Pro 得分 59.0%、Terminal-Bench 2.1 得分 66.0%、MCP Atlas 得分 74.2%。M3 已通过 MiniMax Code、Token Plan 和 API 开放使用,官方表示将在未来 10 天内发布技术报告并开源模型权重。

    from labs.scale.com. Claude Opus 4.7, MiniMax-M2.7, and MiniMax-M3 used Mini-SWE-Agent as scaffolding, with evaluation logic aligned with the official method. NL2Repo: Scores for DeepSeek-V4-pro, Kimi-k2.6, and GLM-5.1 are taken from https://qwen.ai/blog?id=qwen3.7. Other models were evaluated on internal infrastructure with a sandbox configured as 1C2G and a 4-hour timeout. Claude Opus 4.7, MiniMax-M2.7, MiniMax-M3, and Gemini 3.1 Pro used Claude Code scaffolding; GPT-5.5 used Codex scaffoldin

    匹配字段正文

星期四

  1. Modal 官方工程博客

    Modal 完成 3.55 亿美元 C 轮融资,估值 46.5 亿美元

    Modal 宣布完成 3.55 亿美元 C 轮融资,投后估值 46.5 亿美元,由 General Catalyst 和 Redpoint 领投,Menlo、Bain Capital Ventures、Accel 等新投资方加入,原有主要投资方全部跟投。公司称自去年 9 月以来规模增长五倍,年化收入超过 3 亿美元。Modal 定位为面向 AI 负载的云平台,提供弹性推理、智能体运行时、强化学习和批处理任务等能力,Sandboxes 已贡献超过三分之一收入,平台累计启动超过 10 亿个沙箱。

    ing ownership of their models. They're fine-tuning with their own data, running RL, and tuning inference for their own latency, throughput, and cost needs. Open-weight models from DeepSeek, Qwen and others have reached production quality, and inference engines like vLLM and SGLang have matured alongside them. For the first time, the full stack to own and serve your models is there, without sacrificing capability. “Modal powers both our reinforcement learning infrastructure and production inferen

    匹配字段正文

星期三

  1. Qwen Blog精选

    阿里发布 Qwen3.7-Max,面向智能体时代的旗舰模型

    阿里 Qwen 团队发布 Qwen3.7-Max,定位为面向智能体时代的专有模型,可通过阿里云百炼(Model Studio)调用 API。官方称其在编码智能体、通用智能体与推理基准上取得领先或接近 Opus-4.6 Max 的成绩,并支持 Claude Code、OpenClaw、Qwen Code 等多种框架。文中还展示了一次约 35 小时、1158 次工具调用的自主内核优化,最终相对 SGLang Triton 参考实现取得 10.0x 几何平均加速。

    livered the final 1.2x improvement in the last hours. We also ran the same task with several other models under identical conditions. GLM 5.1 reached 7.3x; Kimi K2.6 reached 5.0x; DeepSeek V4 Pro reached 3.3x; Qwen3.6-Plus reached 1.1x. Models that stopped early did so because the agent issued no tool calls for five consecutive rounds — the model concluded it could no longer make progress and voluntarily ended the session. In addition to achieving strong kernel generation results on PPUs, Qwen3.

    匹配字段正文

星期二

  1. Together AI Blog

    大规模推理基准测试:编码智能体

    Together Inference Engine 在 Kimi K2.5 编码智能体负载下,以相同的 4× NVIDIA B200 硬件实现了比 TensorRT-LLM 高 31% 的 TPS,并在饱和时保持约 2 倍更优的 TTFT。测试采用约 45k–200k Token 的长提示词和平均 450 Token 的输出;SGLang 因 TP4 内存不足改用 8× B200。性能提升来自 ThunderMLA、定制内核重写及真实流量下的端到端分析。

    Bar chart titled Coding agents with pink and orange bars on dark background with code snippets behind.

    came from treating inference as a full-stack problem: profiling end-to-end, identifying the most expensive operations, and eliminating them one by one. ThunderMLA. Kimi K2.5 uses DeepSeek's Multi-head Latent Attention (MLA) architecture. Standard implementations run two separate kernel launches per decode step. Our ThunderMLA — part of our ThunderKittens kernel library — fuses these into a single megakernel, eliminating launch overhead and the tail effects between them. On representative decode

    匹配字段正文