vLLM 发布基于 PagedAttention 的开源 LLM 推理与服务库
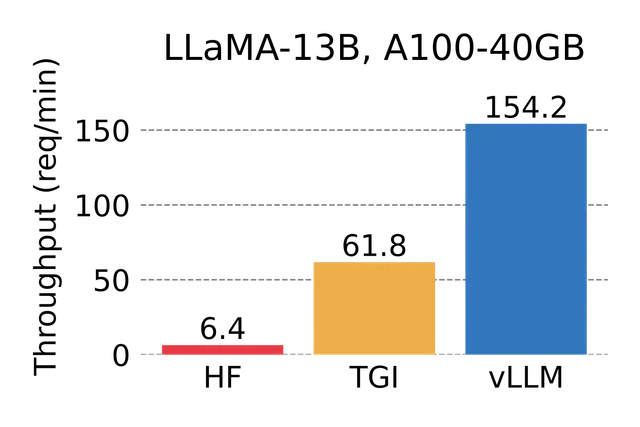
vLLM 发布开源 LLM 推理与服务库,利用 PagedAttention 管理 KV cache,无需修改模型架构即可实现比 HuggingFace Transformers 最高 24x 的吞吐量。实验中其吞吐量比 TGI 最高提升 3.5x,内存浪费降至 4% 以下;LMSYS 部署后将服务所需 GPU 数量减少 50%。
ire team — Siyuan Zhuang, Ying Sheng, Lianmin Zheng (UC Berkeley), Cody Yu (Independent Researcher), Joey Gonzalez (UC Berkeley), Hao Zhang (UC Berkeley & UCSD), and Ion Stoica (UC Berkeley). Related Posts DeepSeek-V4.1-Flash on vLLM: 5x Agentic Throughput Since Day 0 Within three weeks of release, vLLM made DeepSeek-V4.1-Flash 1.9x faster at low concurrency and lifted its throughput 5x on SemiAnalysis AgentX, with SWA bounded replay, CUDA graphs, DeepSeek's new kernels, and vLLM kernel fusions.
匹配字段正文