←搜索结果

按匹配度 · 共 2039 条结果 清除搜索

星期四

  1. Microsoft Research

    微软研究:将物理 AI 推理从机器人卸载到边缘与云端

    微软研究院发布首个针对机器人工作负载的系统性研究,聚焦移动机器人操作任务,评估语义建图与规划、导航、操作三类模型在机载、边缘和云端算力配置下的表现。结果显示,卸载推理可提升响应时间与准确率并延长续航:在内存足够的 GPU 上,建图与规划相比 A100 最多慢 383%,轻量 GPU 上导航的障碍物及时检测下降 30%,VLA 模型准确率下降 50%;用 Raspberry Pi-5 替代机载 GPU 后,Jetson Thor 等较大机载 GPU 最多消耗 160% 的电池。微软同时在 Physical AI Toolchain 中加入物理 AI 推理卸载能力,提供 SO-101 与 UR10e 的示例项目,并演示将 Rho 模型推理卸载到 Jetson Thor 以控制 Mobile Aloha 机器人。

    nalizing physical intelligence at scale. Physical AI Toolchain is an open-source, production-ready framework that integrates Microsoft Azure (opens in new tab) cloud services with NVIDIA’s (opens in new tab) physical AI stack, accelerating robotics and physical AI developers to automate and scale data curation, augmentation, and evaluation across perception, mobility, imitation learning, and reinforcement learning pipelines. We are announcing the addition of an industry-first capability for offl

    匹配字段正文
星期三

  1. The Rundown AI

    Anthropic 与 OpenAI 相隔 90 分钟发布 Claude Opus 5.5 和 GPT-6 Sol、Luna

    Anthropic 发布 Claude Opus 5.5,在 AA 的 Intelligence Index 上以 58 分登顶,超过此前领先的 Fable 5.1 和 GPT-6 Astra 的 53 分,价格比前代低 40%;OpenAI 随后推出 GPT-6 Sol 和 Luna,得分较 5.6 对应版本略有提升,价格减半,Luna 为每百万 token 0.10/0.50 美元,Sol 为 2/10 美元。Anthropic 称 5.5 在其内部对齐基准上取得迄今最好成绩,并改进了被批评的 Claudish 写作风格;这是 Anthropic 提出 pacing 后的首个发布,Sam Altman 表示 pacing 并不意味着停止。

    superintelligence. This conference gives you access to: 3 tracks and 30+ technical breakout sessions 4+ hands-on keyboard labs led by CoreWeave engineers Keynotes from CoreWeave, NVIDIA, Capital One, and more Entertainment from BattleBots, Pitbull, and F1 Image source: Images 2.5 / The Rundown The Rundown: OpenAI says a single internal model has resolved 100+ open math problems since it began training on Aug. 28, and it’s now handing nine top mathematicians an advisory role in how those results

    匹配字段正文

  2. Latent Space

    Anthropic 发布 Claude Opus 5.5,OpenAI 同日推出 GPT-6 Sol 与 Luna

    Anthropic 发布 Claude Opus 5.5,称其为新 Claude 5.5 家族首个模型,多数任务达到 Claude Fable 5.1 水平,运行成本比 Opus 5 低 40%,并已成为 Claude Code 和 Claude 应用的默认模型。OpenAI 约一小时后发布 GPT-6 Sol 和 Luna,定价分别为每百万 token 输入/输出 2 美元/10 美元和 0.10 美元/0.50 美元,均比 GPT-5.6 前代便宜约 50%。Opus 5.5 的系统卡还报告了最多 100 个并行智能体的多智能体扩展结果,Sonnet 5.5 和 Haiku 5.5 将在未来几周跟进。

    nd individuals trying to run large open-weight models with constrained memory, including growing KV caches. Hardware and local deployment were another theme. A hands-on post about NVIDIA DGX Spark described a 15×15×5.05 cm , 1.2 kg system with GB10 Grace Blackwell , 128 GB unified memory , and up to 1 PFLOP FP4 sparse theoretical compute , with NVIDIA claiming support for local inference on models up to 200B parameters with quantization and fine-tuning up to 70B with methods like QLoRA @kimmonis

    匹配字段正文

  3. The Next Platform

    Quantum Elements 用 Orbit 将表面码适配 IBM heavy-hex 架构

    Quantum Elements 与南加州大学在《Nature》发表研究,证明表面码可与 IBM Heron 量子处理器的 heavy-hex 架构配合实现纠错,该处理器有 133-qubit 和 156-qubit 两种配置。研究借助 Quantum Elements 的 Orbit 量子纠错抑制工具、深度高效纠错码、动态解耦与基于 SWAP 的嵌入,实现了方向性亚阈值扩展。Orbit 已于 7 月上线 IBM Qiskit Functions Catalog。

    es. The connectivity of the heavy-hex lattice can be mapped onto other canonical lattices such as the square lattice with constant cost overhead; it is negligible compared to encoding costs.” SPONSORED FEATURE: HPE and NVIDIA help organizations apply accelerated computing, software, enterprise infrastructure, networking, control plane, and services to the workloads and business outcomes that matter most. October 1, 2026 September 30, 2026 AMD Buys World Labs For $8.2 Billion To Get AI Model Cred

    匹配字段正文

  4. Modal 官方工程博客

    Modal 如何服务万亿 token 级编码智能体推理

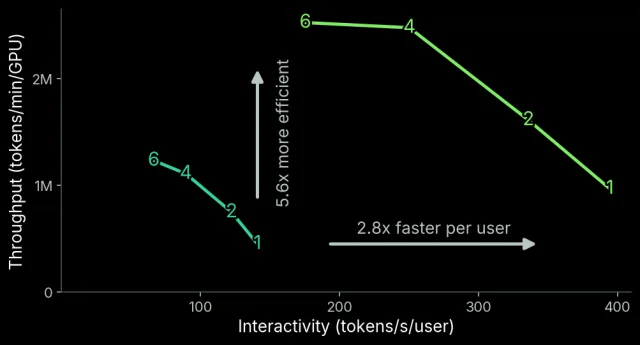
    Modal 官方工程博客复盘了为编码智能体提供推理服务的优化过程,以 Moonshot AI 的 Kimi K2.6 为例,单副本每用户性能提升 2.8 倍、副本整体提升 5.6 倍。他们用 NVFP4 微缩放格式在 B200 上部署约一万亿参数的模型,基于 SGLang 打补丁并回馈上游,通过 DFlash 投机解码、KV cache 量化与 HiCache 扩展缓存,再配合负载感知的有状态路由,把服务扩展到每天处理数千亿 token。相关代码与配置已作为 Modal Auto Endpoints 的开源后端发布。

    re easier to serve. Using multiple processors together requires an interconnection network (interconnect) for communication. The lowest latency, highest bandwidth interconnect for Nvidia GPUs is NVLink. NVLink operates across a group of processors in a “domain” of some size. A single host operating system can support an NVLink domain of up to 8 GPUs. The largest NVLink domains that are generally available comprise 72 accelerators (in a multi-node IMEX domain). Using more accelerators would requi

    匹配字段正文

  5. The Next Platform

    向量搜索已成数据库内建数据类型,但成本账并未消失

    近似最近邻搜索已普遍成为 Postgres、Elasticsearch、OpenSearch、ClickHouse、MongoDB、Redis 等现有数据库中的一种列类型,专用向量数据库的独立价值随之减弱。但成本并未消失:内存占用由向量数量与维度决定,100 万个 1536 维 float32 向量约需 6.1 GB,HNSW 索引可达原始向量的 2-5 倍,量化与磁盘 ANN 成为主要降本手段。

    work with agentic AI applications. If you have a burr under your saddle about something and you have the technical chops, I am always happy to let you have the soapbox for a story. Reach out. SPONSORED FEATURE: HPE and NVIDIA help organizations apply accelerated computing, software, enterprise infrastructure, networking, control plane, and services to the workloads and business outcomes that matter most. October 1, 2026 September 30, 2026 AMD Buys World Labs For $8.2 Billion To Get AI Model Cred

    匹配字段正文

星期二

  1. Interconnects

    与 Epoch AI 的 JS Denain 辩论 RSI、中美差距与模型能力参差

    Interconnects 播客第 19 期,Nathan Lambert 与 Epoch AI 洞察团队负责人 JS Denain 讨论 RSI、中美模型差距与能力参差。JS 认为 OpenAI、Anthropic 公开的博客证据不足以证明 AI 即将自我加速,但 OpenAI 博文中 Codex 研究支出每月增长 2 倍值得关注;两人对 AI 走向均持高度不确定态度。

    得离谱的岗位。”xAI 在招梗图专家之类的,而且更多是零散好玩的东西,而不是大的趋势,至少从我看到的是这样。 00:47:35 Nathan Lambert:是的。我觉得不幸的是,这不会改变。看起来非常像是实验室里的各个团队在数据公司都有联系人,而这一切都是私下进行的,而且这并不……我想就连追踪算力也相当困难,但现在数据中心是一种某种程度上可追踪的体现。而 NVIDIA 是一家上市公司,这就是所做的事情。如果数据公司是上市公司,可能就更容易厘清一些事情了。 00:48:13 JS Denain:同意。 00:48:13 Nathan Lambert:好,我们还有一个应时的话题。你对前沿模型的防护措施怎么看?考虑到在过去 24 小时里,我们得知有三个人使用公开的 Claude 模型入侵了 OpenAI 并获取了内部访问权限,这在我看来简直疯了。你看到这个了吗?这真的让我很惊讶,我们竟然处在这样一个到处漏风的世界里。与此同时,我们却在更加严肃地讨论 RSI 相关的事情。 00:48:46 JS Denain:是的。我简要看到了这个事件。我想我不确定它到底应该在多大程度上算作一个更新,特别是

    匹配字段正文

  2. The Rundown AI精选

    亚马逊封禁 Meta 的 Muse 购物智能体

    亚马逊在 Meta 的 Muse 智能体上线仅 12 天后切断其购物访问,称其未表明身份浏览商店并疑似存储客户登录信息,Meta 否认这些指控。亚马逊表示 Meta 从未告知 Muse 会进入商店,Muse 用户尝试购物时会看到提示,称未经授权的 AI 智能体继续访问违反亚马逊使用条件。此事背后是智能体可能绕开亚马逊赞助商品广告的入口之争,该广告业务规模估计为 560 亿美元。

    XAI released Grok 4.7, its latest update with strong agentic and coding scores, which lands at a 46 on Artificial Analysis’ Intelligence Index, behind Anthropic, OpenAI, and Meta. Nvidia CEO Jensen Huang put the odds of AI ending the world by 2030 at 0%, calling ex-Anthropic researcher Jacob Coxon’s viral warnings “irresponsible.” Meta l aunched Muse connectors for developers, allowing outside apps to plug into its AI agent and creating a directory for the approved connector options. The U.S. FA

    匹配字段正文

  3. AWS Machine Learning

    Tata Elxsi 如何在 AWS 上秒级检测工业安全风险

    Tata Elxsi 在 AWS 上构建了实时工业安全平台 IRIS,在边缘用 AWS IoT Greengrass 和 GPU 服务器抽帧并做首轮过滤,只把安全相关帧和结构化元数据上传云端,使上传帧量减少约 70–80%。平台以 Amazon Kinesis Data Streams 为事件骨干,单部署持续吞吐 2,000–5,000 事件/秒、突发约 15,000 事件/秒,p95 事件摄取延迟低于 200 毫秒,模型推理运行在 Amazon SageMaker AI 的 ml.g5.xlarge 实例上。

    rting, and storage The workflow begins at the edge. IRIS deploys a dedicated edge-compute tier using AWS IoT Greengrass on industrial-grade, GPU-equipped edge servers, for example NVIDIA Jetson AGX Orin or equivalent. Each server is installed at the facility and connected to the camera network over RTSP/ONVIF. At the edge, IRIS extracts frames at a configurable rate of 2-5 frames per second and applies motion-based filtering. It then runs a lightweight first-pass model to identify frames that co

    匹配字段正文

  4. Latent Space

    小米发布 MiMo-V2.6-Pro 与 Flash 开源全模态模型,训练成本约 300 万美元

    小米发布 MiMo-V2.6 系列开源全模态模型,其中 MiMo-V2.6-Pro 为 1.02T 总参数、42B 激活参数,采用 MIT 许可,Artificial Analysis 称其以 46 分登顶开源权重模型智能指数。技术报告显示其 RL 训练在 130 小时、75B token 上花费约 260 万美元,并计划开源环境代码与训练配方,但 7k+ 任务数据集尚未发布。

    xed-precision quantization averaging 2.38 bits/weight , including custom CUDA kernels in patched llama.cpp. On the edge/local side, @vikhyatk released Parakeet Redux , compressing NVIDIA’s speech model from 1.2GB to 178MB , running at 113x realtime on CPU , while beating the base model on 25-language FLEURS and staying within 0.3 WER on English. Agents, Security, and Human-in-the-Loop Control Computer-use systems are becoming more productionized, but security is now central : Patrick Wardle repo

    匹配字段正文

  5. Black Forest Labs Blog精选

    Black Forest Labs 发布 FLUX 3 Action:7B 开源世界动作模型用于机器人控制

    Black Forest Labs 发布 FLUX 3 Action,一个从多模态 FLUX 3 主干衍生的 7B 开源权重世界动作模型,在 RoboLab-120 榜单上以不到此前最佳开源模型一半的参数量取得 38.3% ± 0.38 的成功率,速度最高提升 3.95 倍。该模型在图像、视频和音频数据上预训练,其中视频占训练 token 的 95% 以上,再通过联合视频-动作训练和针对目标本体的微调适配动作空间。报告还分析了将其与 GPT 6 Astra 等推理模型组合的混合方案,发现快速控制能让具身推理更省时省钱,每美元成功率最高提升 53.64%。

    osmos 3 Nano in FP8 across consumer, workstation and datacenter GPUs. 1Yang et al. 2026, RoboLab: A High-Fidelity Simulation Benchmark for Analysis of Task Generalist Policies. ↩ 2NVIDIA et al. 2026, Cosmos 3: Omnimodal World Models for Physical AI. ↩ 3Intelligence et al. 2025, π0.5: A Vision-Language-Action Model with Open-World Generalization. ↩ π0.5 was evaluated only in BF16; both precision views show its BF16 results. FLUX 3 Action; Cosmos 3 Nano; π0.5; Previous Pareto front; New Pareto fro

    匹配字段正文

  6. Thomas Wolf

    Thomas Wolf 列出约十周内三十余个开源模型发布,回应开源正在消亡的说法

    Hugging Face 的 Thomas Wolf 在 X 上列出 Dylan Patel 访谈之后约十周内发布的开源模型清单,包括 Moonshot Kimi K3、Qwen3.8-Max、DeepSeek V4-Pro、腾讯 Hy4、GLM-5.3 和上海 AI Lab Atria Dawn 等三十余项,并指出其中多个达到前沿规模,如 Kimi K3 的 2.8T、Qwen3.8-Max 的 2.4T、DeepSeek V4-Pro 的约 1.6T。该推文引用的访谈中,Dylan Patel 称有中国模型实验室告知推理厂商下一代模型将不再开源、改为授权,并称开源正在快速消亡。

    Jul 23 DeepSeek - V4-Flash-0731 - Jul 31 Meta - Muse Spark 1.2 / Muse Code - Aug 5 Liquid AI - LFM2.5-2.6B - Aug 6 inclusionAI - Ling 3.0 Tiny - Aug 6 Meta - Muse Glimmer - Aug 10 NVIDIA - Nemotron 3.5 Lightning - Aug 11 Liquid AI - LFM2.5-VL-3B - Aug 12 Cohere - North Micro Vision Instruct - Aug 12 DeepSeek - V4-Pro-0813 - Aug 13 Qwen - Qwen3.8-27B - Aug 14 Qwen - Qwen3.8-Max / 2.4T-A95B - Aug 14 https://t.co/vC8M5B2jY1 - GLM-5.3 - Aug 14, weights Aug 28 Dots - Dots3-Note Preview - Aug 14 DeepR

    匹配字段正文

  7. The Next Platform

    IDC:二季度全球服务器收入达 1663.2 亿美元,GPU 加速机型占 52.5%

    IDC 数据显示,2026 年第二季度全球服务器收入达 1663.2 亿美元,同比增长 52%,环比增长 35.6%。其中 GPU 加速系统收入 874 亿美元,占服务器节点与机架级系统支出的 52.5%,GPU 加速机平均售价 17.022 万美元,同比上涨 43.5%,但出货量同比下降 10.7% 至 513,453 台。XPU 系统收入增长 3.4 倍至 275 亿美元,加速机型以 16.1% 的出货量占比贡献了 69.1% 的收入。

    ems with memory coherence across all machines in the rack. You can know this because a Grace-Blackwell NVL72 rackscale system probably costs somewhere around $4 million or so with Nvidia B200 GPUs, and the inference-tuned NVL72 using B300 GPUs costs $5 million or so, give or take a million dollars depending on who you ask. That ASP for GPU systems given by IDC implies a very large number of low-end systems using cheaper PCI-Express cards, like Nvidia’s RTX Pro 6000. A four-way node using this cl

    匹配字段正文

  8. SemiAnalysis

    MoE 模型推理的计算与数据搬运:结构、流程与高效服务

    SemiAnalysis 梳理了 MoE 模型映射到推理硬件时的计算与数据搬运问题,指出 MoE 改变了服务结构与推理经济性:每个 token 激活的张量不同,对本地带宽、网络链路和内存搬运的要求也不同。文章把推理流程拆为 Prefill、Midfill、Decode attention、Decode experts 四个阶段,并讨论聚合与分离部署的取舍。

    e, and scheduling contribute to useful throughput. The best place to begin is the service as a whole. Inference runs inside a cluster coordinated by an orchestration layer such as NVIDIA Dynamo, Mooncake, or a custom scheduler. These work closely with inference servers like vLLM or SQlang, and those also have their own orchestration features. This article will not go into the details of how you work with the orchestration software or which you should choose. The article aims to provide an overvi

    匹配字段正文

星期一

  1. Interconnects

    开放模型当前的力量格局:中国实验室为何领先

    Interconnects 作者 Nathan Lambert 公开其为美国国会成员及幕僚准备的开放权重模型简报讲稿,梳理中美在开放模型上的力量对比。文中称自 2025 年 4 月起中国 AI 公司已是开放权重模型的明显领先者,Hugging Face 下载量上中国约为美国的 2 倍(3.2B 对 1.6B),Artificial Analysis 智能指数上中国开放模型领先美国同类,中国开放权重模型约落后美国闭源前沿 2-5 个月。作者还引用 OpenRouter 数据称开放模型周处理量从 2025 年 9 月的约 1T tokens 增至如今的约 80T tokens,中国模型份额从约 70% 升至 80% 以上,并认为知识蒸馏只能解释 1-2 个月的差距。

    EleutherAI’s Pythia models. Open-weight, open-source, and every other label for a model – including closed models primarily offered via an API – exist on a spectrum. For example, Nvidia’s Nemotron models are far more open than most open-weight models, releasing large quantities of their training data under permissive licenses, but they’re not fully open-source because they do not release all of the data. Closed models also exist on a spectrum based on what information the API reveals and the te

    匹配字段正文

  2. LiveKit 产品与工程博客

    LiveKit 对比 Pipecat:实时语音与视频 AI 智能体开源框架怎么选

    LiveKit 官方博客对比了实时语音与视频 AI 智能体两大开源框架 LiveKit Agents 与 Pipecat,指出前者基于自家开源 WebRTC 与 SIP 服务、抽象层级更高,后者不预设传输层、需自行逐级组装 pipeline。文章还说明 TEN Framework、Dograh、Vision Agents、Vocode 的定位,并从语言支持、维护活跃度、上手速度和生产就绪度四方面给出选型建议。

    running voice agents with their own customers: Salesforce, Zocdoc, SAP, telli. Pipecat's lean toward companies that build tooling or reference architectures for other developers: NVIDIA's Blueprint, AWS, Anthropic 3. Can I get a working agent going today? When evaluating each framework it's important that you can easily build (and reason about the code for) a voice or video agent. Given AI-augmented development, a developer should be able to get an agent working in a day with either. Independen

    匹配字段正文

星期六

  1. Data Center Knowledge

    AI Infra Summit 探讨太空数据中心:技术与成本障碍仍待突破

    在 AI Infra Summit 上,Viasat、Cowboy Space、Star Catcher 等企业高管与美国空军 CIO 讨论了轨道数据中心的落地障碍:散热、上下行带宽和发射成本。Viasat 的 Sumeet Singh 指出,发射成本需从每公斤 2500 至 3000 美元降至约 200 至 500 美元才具经济性。美国空军 CIO Deepak Sachdeva 表示,该技术尚未满足全球作战所需的延迟、韧性与安全要求,建议先做概念验证。

    经准备好了。但从本质上具有全球性的作战需求来看,我认为还有一些工作要做,”他说。“在我看来,最好的方法是进行某种概念验证。” 相关报道:数据中心太空竞赛:Orbital的卫星能否消除疑虑? Singh所在的公司Viasat希望参与新兴的轨道数据中心生态系统,他表示,该行业必须在技术和商业上逐步证明自己。他提到StarCloud于2025年11月发射了一颗搭载Nvidia H100 GPU的卫星,认为这是一个积极信号,同时指出单GPU演示与兆瓦级和吉瓦级设施相去甚远。“我们突然谈论兆瓦级和吉瓦级数据中心。我认为我们需要中间验证点……介于两者之间、拥有100至500千瓦级算力的东西,”他说。 Singh补充说,其他关键里程碑包括确保有足够的发射能力将这些系统送入轨道,以及证明客户确实会购买太空算力。 Bergin也认同需要“爬、走、跑”的渐进过程,她描述了公司如何先在地球上验证技术,然后再转向太空演示。“这个行业里有很多人倾向于只说,‘这就是我们要建的东西,它会自然而然地实现,’”她说。“我认为从轨道计算的角度来看,那些渐进步骤是什么?我们如何从以单个H100作为原型、运行在5%到10%的

    匹配字段正文

星期五

  1. Ed Zitron 长文 / Where’s Your Ed At

    AI 债务仇恨者指南(上):超大规模厂商与 neocloud 的烧钱困局

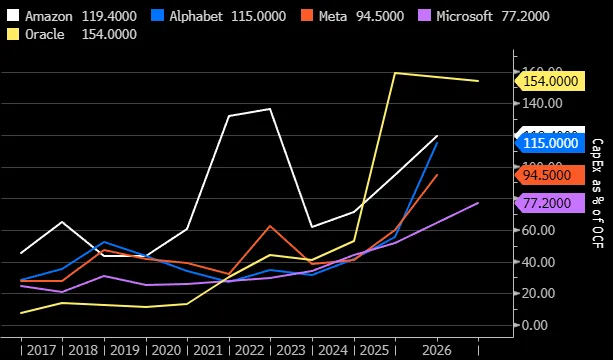
    Ed Zitron 在《AI 债务仇恨者指南(上)》中指出,Oracle、Google、Amazon 已现金流为负,Meta 紧随其后,AI 数据中心的高额资本支出正吞噬几乎全部营收。neocloud 新贵同样大举借债建设吉瓦级数据中心,收入却只是支出的零头。2026 年 AI 相关债务发行规模已超 5000 亿美元。

    e, Google and Amazon going cashflow negative (with Meta not far behind) in pursuit of an indeterminately-large opportunity to sell AI software or rent AI chips (bought from either NVIDIA or Broadcom, see my hater’s guides for more) to either Anthropic and OpenAI or, in Google’s case, Meta. To reiterate what I’ve been saying for a while, big tech has a few issues with the AI buildout: AI chips are extremely expensive; AI data centers take a great deal of time to build and energize; AI services ar

    匹配字段正文

  2. SemiAnalysis

    SemiAnalysis 复现 Engram 架构并实测 DRAM/SSD 卸载

    SemiAnalysis 复现了 DeepSeek 的 Engram 架构,在 fineweb-edu 上以约 6E18 FLOPs 每轮训练,观察到与原文一致的 U 型扩展规律,Engram 优于纯 MoE 基线。其 DeepSeek-V4.1-Flash 配置中 Engram 约占 189 GiB 内存,改用 mmap 文件并卸载到 SSD 后,B200 上 DRAM 方案在约 125 tokens/s/user 时每美元可产出 1.21 亿 token,SSD 仅 5200 万,作者认为生产环境中 SSD 卸载并不划算。在 B300 上启用 Engram 卸载可从 TP4 切到 TP2,帕累托曲线提升最多 1.6 倍。

    nstraint, NVMe offers another tier. Recommendation systems already cache frequently or recently accessed embedding rows in faster memory while backing colder rows with SSDs. After NVIDIA roadmap had to change due to massively despec’ing Rubin Ultra from 1024GB to now 200GB of HBM per chip, model architecture optimizations like emgram maybe helpful. Our DeepSeek-V4.1-Flash configuration uses roughly 189 GiB of memory for Engram. We replace it with a memory-mapped (mmap) file and measure serving p

    匹配字段正文

  3. The Register

    KDE 迎来 30 周年,Akademy 大会出现 AI 原生桌面提案

    KDE 在奥地利格拉茨科技大学举行的 Akademy 大会上迎来 30 周年,会上出现一份 AI 原生桌面提案,设想以加密、厂商无关的个人模型 Kadai 为内核,让 Plasma 按用户、设备和时刻组装每个 Activity。提案称 Plasma 的 Activities、Plasmoids 与脚本接口适合这一方向,但需上游加入声明式协调、按控件能力与更丰富的 Activity 元数据。AI 评论者 David Gerard 指出该提案与 2025 年 12 月发布的 Resonant Computing Manifesto 相似。

    ks It won't kill you, or humanity, to get off the AI upgrade treadmill New models arrive so fast, we already have more new tech than it's possible to understand in a career Cisco, Nvidia team up to build fatter, faster pluggable If you thought 1.6 Tbps was fast, just wait, Cisco's USFP targets 12.8 Tbps in a single optical pluggable TOP STORIES Anthropic asks users to stop being mean to Claude; '123456' password linked to Denmark data breach affecting 8.8M people; Microsoft and Anthropic play in

    匹配字段正文