←Search results

By relevance · Total 566 results Clear search

Friday

  1. OpenRouter

    Krea 3 launches on OpenRouter with support for 1–4 reference images and native 2K editing

    Krea 3 is now live on OpenRouter. It is Krea AI's new image editing model, which can accept 1–4 reference images and a prompt, and returns natively 2K edited images, with most edits completing end-to-end in under 8 seconds. Pricing is $0.03 per 1K image and $0.06 per 2K image; reference images cost $0.02 per 1K image and $0.07 per 2K image. thinking_mode defaults to fast; when more prompt reasoning is needed, it can be set to high (an additional $0.02). It uses the same Images API as other image models on OpenRouter, so migration only requires changing the model ID.

    Krea 3 is now live on OpenRouter. It is Krea AI's new image editing model, which can accept 1–4 reference images and a prompt, and returns natively 2K edited images, with most edits completing end-to-end in under 8 seconds. Pricing is $0.03 per 1K image and $0.06 per 2K image; reference images cost $0.02 per 1K image and $0.07 per 2K image. thinking mode defaults to fast; when more prompt reasoning is needed, it can be set to high (an additional $0.02). It uses the same Images API as other image

    Matched fieldsSummary
  2. Analytics India Magazine

    NVIDIA Expands Nemotron Model Family with New Super VL and Two Bolt Models

    NVIDIA has added three models to the Nemotron open-source model family, covering enterprise workflows, local AI agents, and conversational applications across data centers, desktops, and edge devices. These include the 120-billion-parameter Nemotron 3.5 Super VL, which NVIDIA claims delivers up to 5x the throughput of the next-best comparable model, with accuracy approaching that of its largest reasoning model at roughly one-fifth the parameter count; there are also two small models in the Nemotron 3.5 Bolt series: 74B-A9B 24GB for everyday agent tasks on RTX and DGX Spark, and E4B 4GB for conversational and physical AI agents. Super VL and Bolt 74B-A9B are already available, and Bolt E4B is scheduled for release on October 23.

    NVIDIA has added three models to the Nemotron open-source model family, covering enterprise workflows, local AI agents, and conversational applications across data centers, desktops, and edge devices. These include the 120-billion-parameter Nemotron 3.5 Super VL, which NVIDIA claims delivers up to 5x the throughput of the next-best comparable model, with accuracy approaching that of its largest reasoning model at roughly one-fifth the parameter count; there are also two small models in the Nemot

    Matched fieldsSummary、Body

  3. The Guardian Technology

    Meta releases open-weight model Muse Spark Open

    Meta released the open-weight model Muse Spark Open on Thursday, saying its capabilities can match and in some scenarios surpass comparable products from Chinese vendors. Meta AI head Alexandr Wang called it the most capable U.S. open-weight model to date; the model targets coding and agentic tasks, excels at long-horizon tasks, complex software engineering and multi-step reasoning, and has built-in safety safeguards. The model is optimized for the Apple M5 Ultra chip, and users can run it on the desktop with two Mac Studios equipped with that chip.

    Meta released the open-weight model Muse Spark Open on Thursday, saying its capabilities can match and in some scenarios surpass comparable products from Chinese vendors. Meta AI head Alexandr Wang called it the most capable U.S. open-weight model to date; the model targets coding and agentic tasks, excels at long-horizon tasks, complex software engineering and multi-step reasoning, and has built-in safety safeguards. The model is optimized for the Apple M5 Ultra chip, and users can run it on th

    Matched fieldsSummary、Body

  4. Hugging FaceSelected

    Hugging Face Releases Beam: A 501B Open Source Model Supporting 1M Context and Self-Hosting

    Hugging Face has released Beam, a 501B-parameter sparse MoE open source model aimed at long-text reasoning and agent tasks with 1M context, activating only about 23B parameters per token. The model uses 52 layers of hybrid attention, with 43 layers using a 512-token sliding window and 9 layers using global attention; the KV cache grows by 36 KiB per token, about one-sixth that of a full-attention approach. The official release provides three checkpoints—BF16, FP8, and NVFP4; NVFP4 can compress the weights from about 1 TB to about 280 GB, and day-0 support is already available in transformers, vLLM, and SGLang.

    Hugging Face has released Beam, a 501B-parameter sparse MoE open source model aimed at long-text reasoning and agent tasks with 1M context, activating only about 23B parameters per token. The model uses 52 layers of hybrid attention, with 43 layers using a 512-token sliding window and 9 layers using global attention; the KV cache grows by 36 KiB per token, about one-sixth that of a full-attention approach. The official release provides three checkpoints—BF16, FP8, and NVFP4; NVFP4 can compress t

    Matched fieldsSummary、Body

  5. Ollama BlogSelected

    Reflection's Open-Weight Model Beam Launches on Ollama, Free for a Limited Time

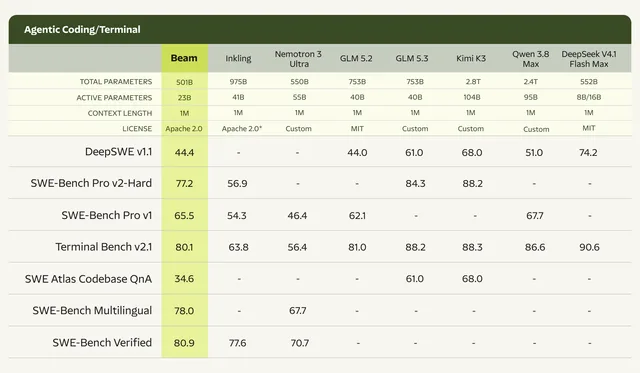
    Reflection's first open-weight model, Beam, is officially released, offered free for a limited time with Ollama as a day-zero partner and with zero data retention (ZDR). Beam is an MoE model with approximately 501 billion total parameters, about 23 billion activated per token, and a 1 million token context window. It targets software engineering, reasoning, and long-horizon agentic tasks, and is released under the Apache 2.0 license. Users can run beam:cloud via Ollama Cloud and connect it to tools such as Claude Code, Codex, and OpenCode.

    Beam agentic coding benchmarks

    Reflection's first open-weight model, Beam, is officially released, offered free for a limited time with Ollama as a day-zero partner and with zero data retention (ZDR). Beam is an MoE model with approximately 501 billion total parameters, about 23 billion activated per token, and a 1 million token context window. It targets software engineering, reasoning, and long-horizon agentic tasks, and is released under the Apache 2.0 license. Users can run beam:cloud via Ollama Cloud and connect it to to

    Matched fieldsSummary、Body

  6. Baseten Engineering BlogSelected

    Reflection's Open-Weight Model Beam Launches on Baseten: 501B MoE with 1M Context

    Reflection's first open-weight model, Beam, is now available on the Baseten platform, with day-0 support through Baseten Model APIs and Dedicated Inference. Beam uses a MoE architecture with 501B total parameters and 23B activated per token, a context window of up to 1 million tokens, and is aimed at coding and agent workflows. During training, Reflection used longer RL rollouts and added a length penalty to encourage the model to complete tasks with fewer tokens; users can also adjust reasoning effort via a parameter to control how much reasoning the model invests.

    Beam

    Reflection's first open-weight model, Beam, is now available on the Baseten platform, with day-0 support through Baseten Model APIs and Dedicated Inference. Beam uses a MoE architecture with 501B total parameters and 23B activated per token, a context window of up to 1 million tokens, and is aimed at coding and agent workflows. During training, Reflection used longer RL rollouts and added a length penalty to encourage the model to complete tasks with fewer tokens; users can also adjust reasoning

    Matched fieldsSummary、Body

  7. Artificial Analysis full articleSelected

    Reflection Releases Its First Model Beam, Scoring 30 on the Artificial Analysis Intelligence Index

    Reflection has released its first model, Beam, an open-weight model with 501B total parameters and 23B activated parameters. It scores 30 on the Artificial Analysis Intelligence Index, ranking second among US open-weight models, behind only Meta's Muse Spark Open (39) and ahead of NVIDIA's Nemotron 3.5 Super VL (26). Beam consumes about 26k output tokens per Intelligence Index task, of which about 19k are used for reasoning and 7k for answering; it scores 48.5% on AutomationBench-AA, but only 3.0% on Terminal-Bench 4.0. On AA-Omniscience, it answers 33% of questions correctly, with a hallucination rate of 47% and a net index score of 1.5.

    Reflection has released its first model, Beam, an open-weight model with 501B total parameters and 23B activated parameters. It scores 30 on the Artificial Analysis Intelligence Index, ranking second among US open-weight models, behind only Meta's Muse Spark Open (39) and ahead of NVIDIA's Nemotron 3.5 Super VL (26). Beam consumes about 26k output tokens per Intelligence Index task, of which about 19k are used for reasoning and 7k for answering; it scores 48.5% on AutomationBench-AA, but only 3.

    Matched fieldsSummary、Body

Thursday

  1. OpenRouter

    NVIDIA Nemotron 3.5 Super VL Launches on OpenRouter

    NVIDIA Nemotron 3.5 Super VL is now available on OpenRouter. It is an open-source 120B-A12B multimodal model designed for long-running agents that need to observe, reason, and act across text, images, documents, GUIs, and video, with support for a 1M context. The model uses a Hybrid Mamba-Transformer MoE architecture and supports multi-token prediction to speed up output, targeting scenarios such as document intelligence, web research, customer service, and video understanding.

    Matched fieldsSummary