LMSYS Releases SGLang AWS Trainium Plugin Beta
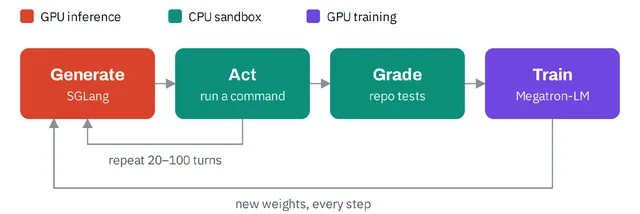
LMSYS, in collaboration with AWS, has released the SGLang Trainium plugin Beta, built on the newly released TorchNeuron, supporting LLM inference serving and RL rollout generation on Trainium2 and Trainium3. Initial coverage includes Qwen3 (dense), Qwen3-MoE-30B-A3B, DeepSeek-V2-Lite, GLM-4, and GLM-5.2/5.3, and supports data parallelism, tensor parallelism, expert parallelism, Radix Cache, BF16/FP8, and asynchronous scheduling. In the first end-to-end heterogeneous RL run, SGLang generated rollouts for Qwen3-MoE-30B-A3B on Trainium3, while Miles trained a GRPO policy with Megatron on a single H200 node. The Beta is currently limited to a small number of teams.
LMSYS, in collaboration with AWS, has released the SGLang Trainium plugin Beta, built on the newly released TorchNeuron, supporting LLM inference serving and RL rollout generation on Trainium2 and Trainium3. Initial coverage includes Qwen3 (dense), Qwen3-MoE-30B-A3B, DeepSeek-V2-Lite, GLM-4, and GLM-5.2/5.3, and supports data parallelism, tensor parallelism, expert parallelism, Radix Cache, BF16/FP8, and asynchronous scheduling. In the first end-to-end heterogeneous RL run, SGLang generated roll
Matched fieldsSummary