Together AI Details GPU Cluster Auto-Repair: From GPU Failure to Healthy Node
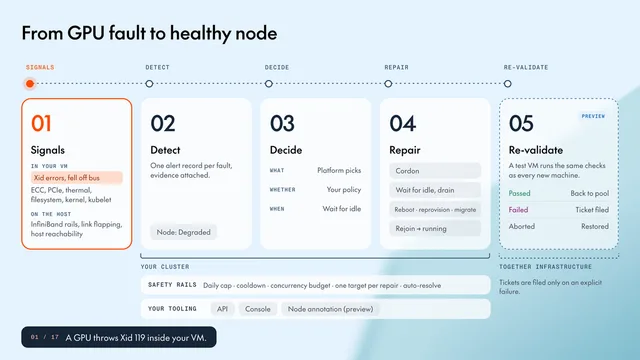
Together AI introduces its GPU cluster auto-repair system, which now officially offers passive health checks, repair recommendations, auto-repair policies (including per-fault and per-node authorization), wait-for-idle controls, escalation ladders, safety guardrails, and API and console repairs; custom detection onboarding based on node labels remains in preview. The system is divided into four stages: detection, decision, repair, and re-verification. The first three stages run within the user's cluster, while re-verification is performed on the Together side on the freed-up physical machines. The platform maps each signal to the lightest repair action, and users can decide whether to execute automatically and how long to wait; after the same action is repeated twice for the same fault, it automatically escalates one level.
#Product updates#English text is being prepared.


